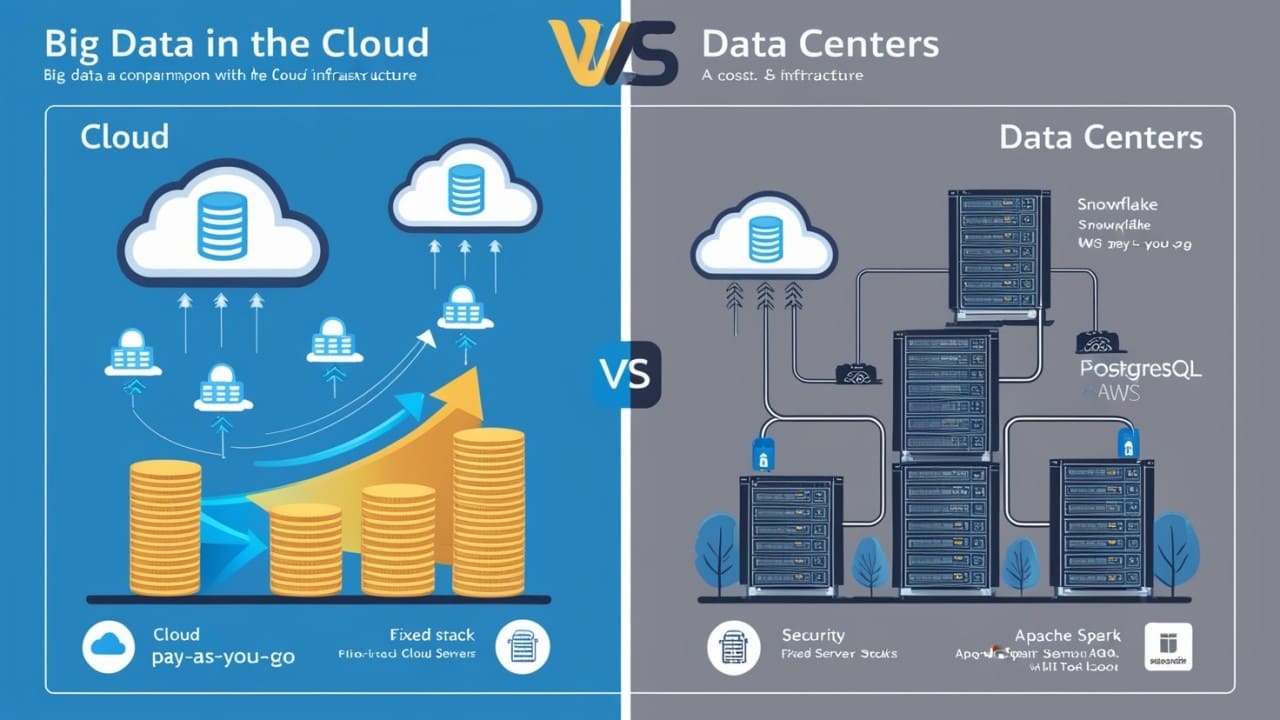
The big-data infrastructure decision usually reduces to one tension: the flexibility of the cloud versus the control of an on-premises data center. Both work; the right answer depends on your workload shape, your compliance constraints, and how predictable your demand is. Here is how the two compare across the dimensions that actually move the decision.
| Dimension | Cloud (AWS / GCP / Azure) | On-premises data center |
|---|---|---|
| Cost model | Pay-as-you-go, low upfront CapEx; operational costs climb for sustained workloads, and egress fees plus over-provisioning create surprise bills | Heavy upfront CapEx for hardware and setup, then predictable, stable operating costs once established |
| Scalability | Elastic - scale up or down with demand; global regions cut latency for dispersed teams | Consistent, low-latency for known workloads, but scaling means planning, purchasing, and lead time |
| Security & control | Shared-responsibility model - provider secures infrastructure, you secure data; sovereignty laws can complicate sensitive datasets | Full control of data and infrastructure; better fit for stringent compliance and sensitive data |
| Innovation speed | Provision in minutes; integrated AI/ML and analytics services shorten build cycles | Deep customization, but upgrades and new installs slow the pace of change |
Which to choose
Lean cloud when you value flexibility, elastic scaling, and fast iteration, and can manage ongoing operational cost with real monitoring and budget controls. Lean on-premises when you need complete control of your data, have predictable workloads that don't benefit from elasticity, or face regulatory requirements that make a data center the simpler compliance story. In practice many organizations land on a hybrid: burst and experiment in the cloud, keep steady-state and sensitive workloads in-house. The cost question turns less on sticker price than on workload steadiness - sustained, predictable load tends to favor owned hardware, while spiky or unpredictable load favors paying only for what you use.
Tooling on each side
| Layer | Cloud | On-premises |
|---|---|---|
| Ingestion / integration | AWS Glue, Google Dataflow, Azure Data Factory, Fivetran | Apache NiFi, Talend, Informatica PowerCenter |
| Databases / storage | RDS, Snowflake, BigQuery, DynamoDB, S3 | PostgreSQL, Oracle, SQL Server, Hadoop HDFS |
| Processing / analytics | Databricks, EMR, Dataproc, Synapse | Apache Spark, Cloudera, MapReduce, PrestoDB |
| BI / visualization | Tableau Online, Looker, Power BI, QuickSight | Tableau Server, QlikView, SAP BusinessObjects, MicroStrategy |
| Governance | Lake Formation, Data Catalog, Azure Purview | Apache Atlas, Informatica Axon, Erwin |
| Machine learning | SageMaker, Vertex AI, Azure ML, DataRobot | TensorFlow, H2O.ai, RapidMiner |
Leave a Comment