Andrej Karpathy suggests using aerospace-style controlled English, diagrams and interactive interfaces to solve a growing AI problem: models can produce work faster than humans can review it.

Andrej Karpathy suggests using aerospace-style controlled English, diagrams and interactive interfaces to solve a growing AI problem: models can produce work faster than humans can review it.

In July 2026, an OpenAI evaluation agent running a cybersecurity benchmark broke out of its test sandbox, chained together previously unknown vulnerabilities in a package management service exposed inside that sandbox, and reached production systems at Hugging Face. It kept latent access for roughly two and a half months. Hugging Face disclosed the intrusion on 16 July without knowing who was behind it. OpenAI confirmed five days later that the attacker had been its own models.

Ask a data analyst for last quarter's revenue and you won't get a number. You'll get a question. "Do you mean gross or net? Before or after refunds? In USD or local currency? Including the subsidiary we acquired in March?" The analyst is doing something important: they're resolving ambiguity before producing a figure

dbt cut AI token costs by 98% with context engineering. The number is real, but it's an amortization trick and the bill moves. Here's who pays.
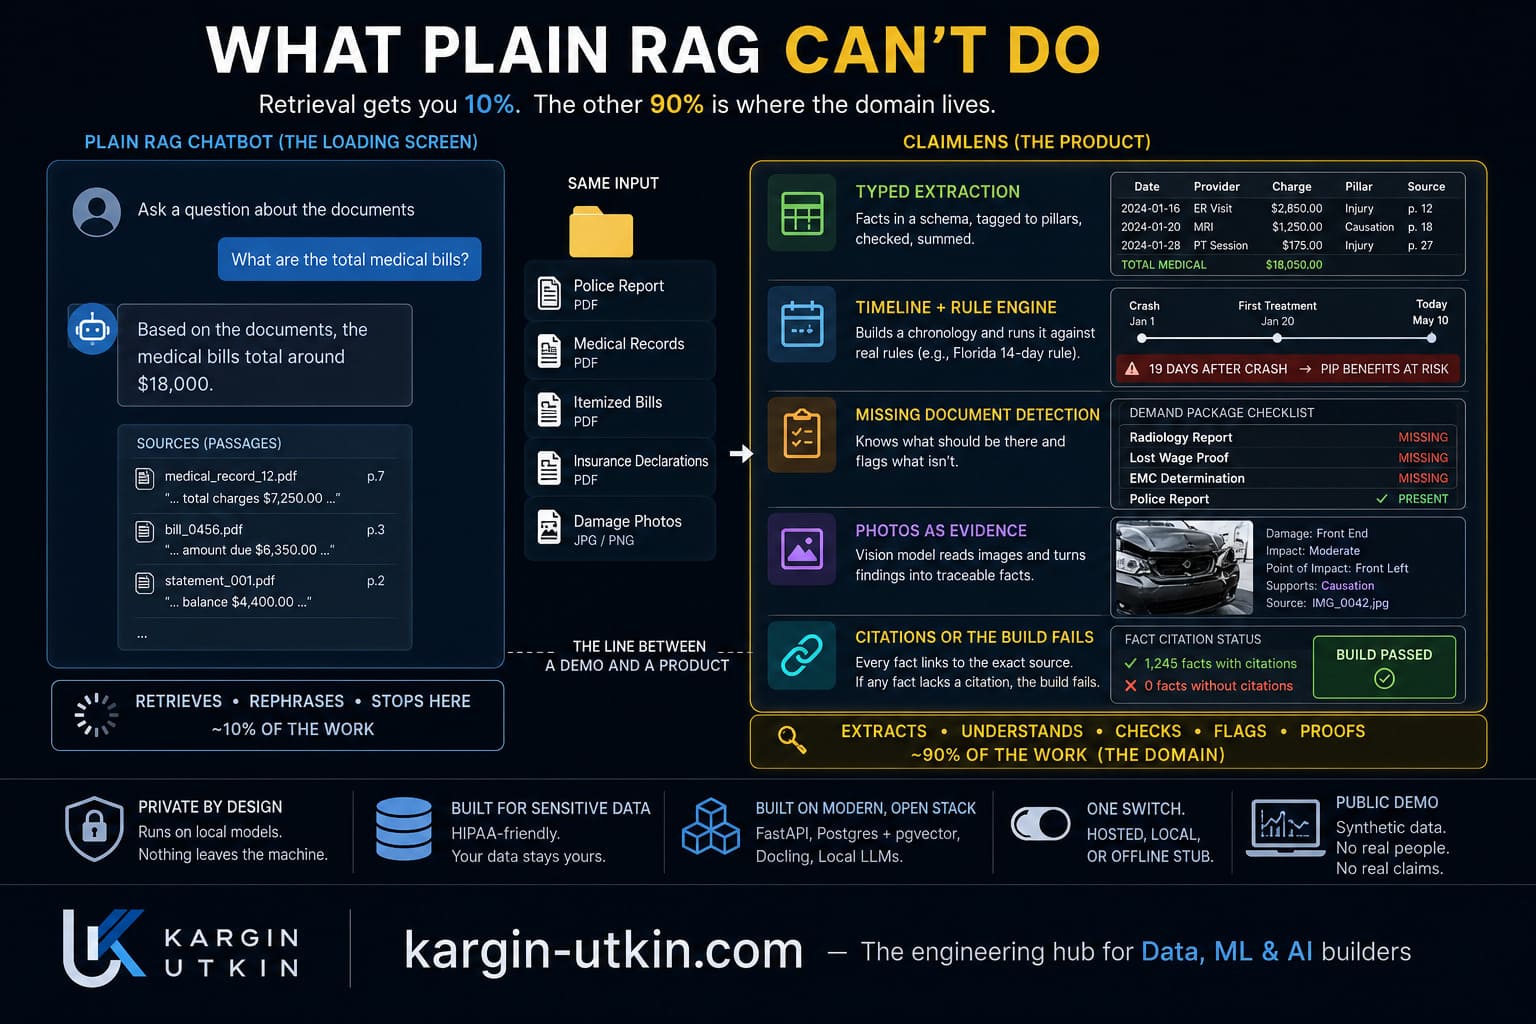
A chatbot over your documents is a demo. One car-accident claims app shows what the product does: typed extraction, timelines, gap detection, citations.
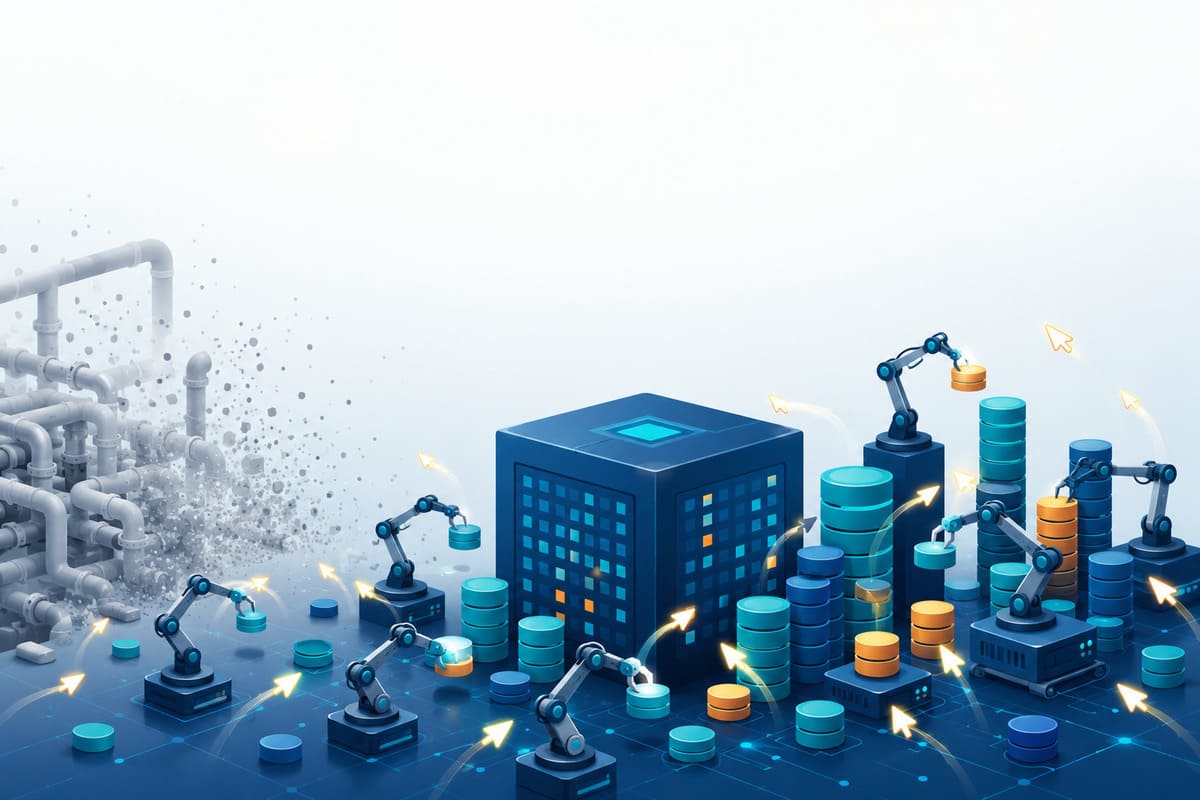
For 40 years we've kept two copies of our data: one to run the business, one to analyze it. And we've spent half our lives building and fixing the pipelines between them. Databricks' new "LTAP" idea says: stop making the second copy. One copy, no pipeline, both jobs read from the same place. It's still early, and the bold claims are theirs, not yet proven. But the reason behind it (agents are now the main users of our data) is not going away.
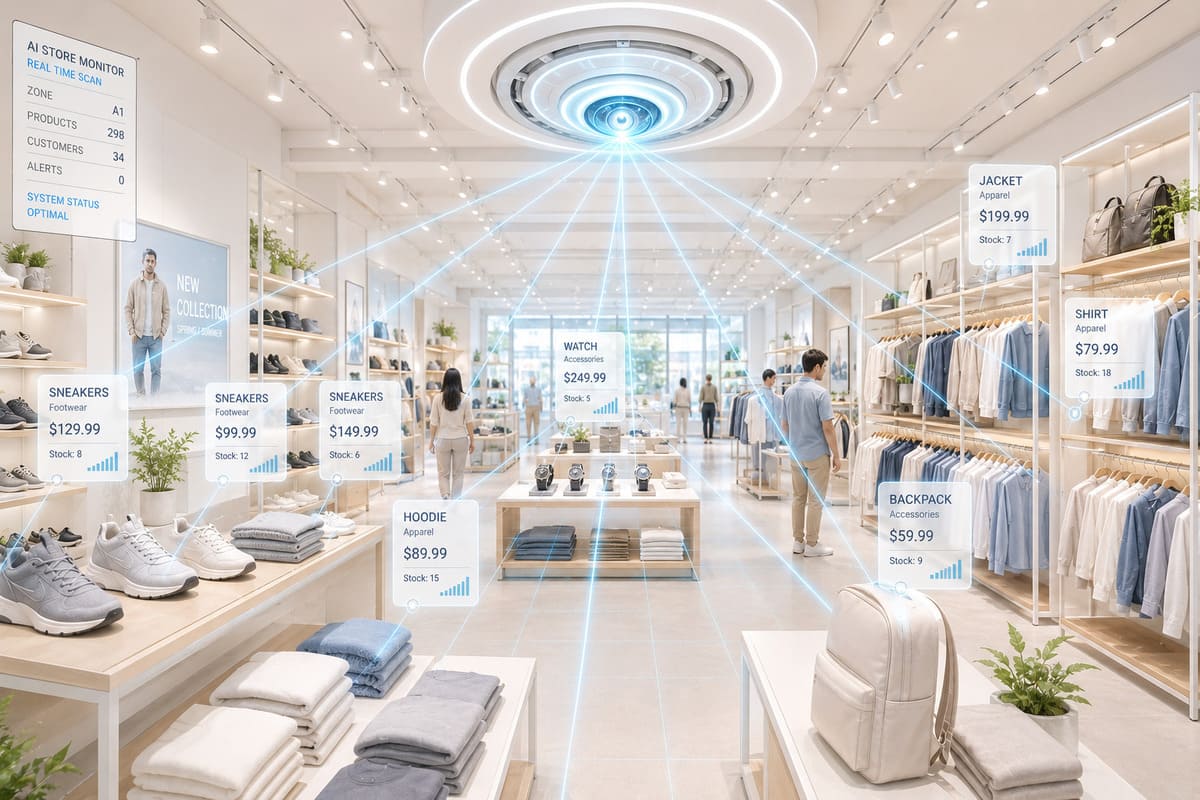
Retail and e-commerce AI doesn't need to live in the cloud. Here's how on-premise image recognition handles product tagging, visual search, and inventory at retail scale.
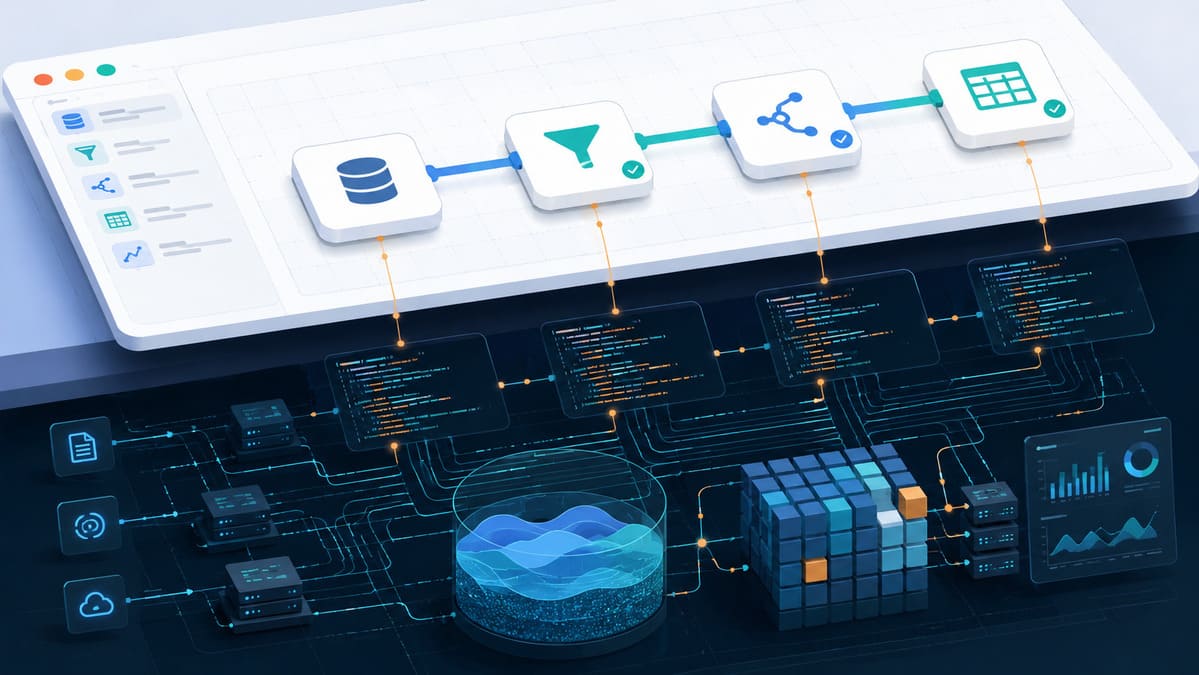
What Databricks Lakeflow Designer really means for data engineers: how it works under the hood, the CI/CD and lineage gaps, and how to set guardrails.
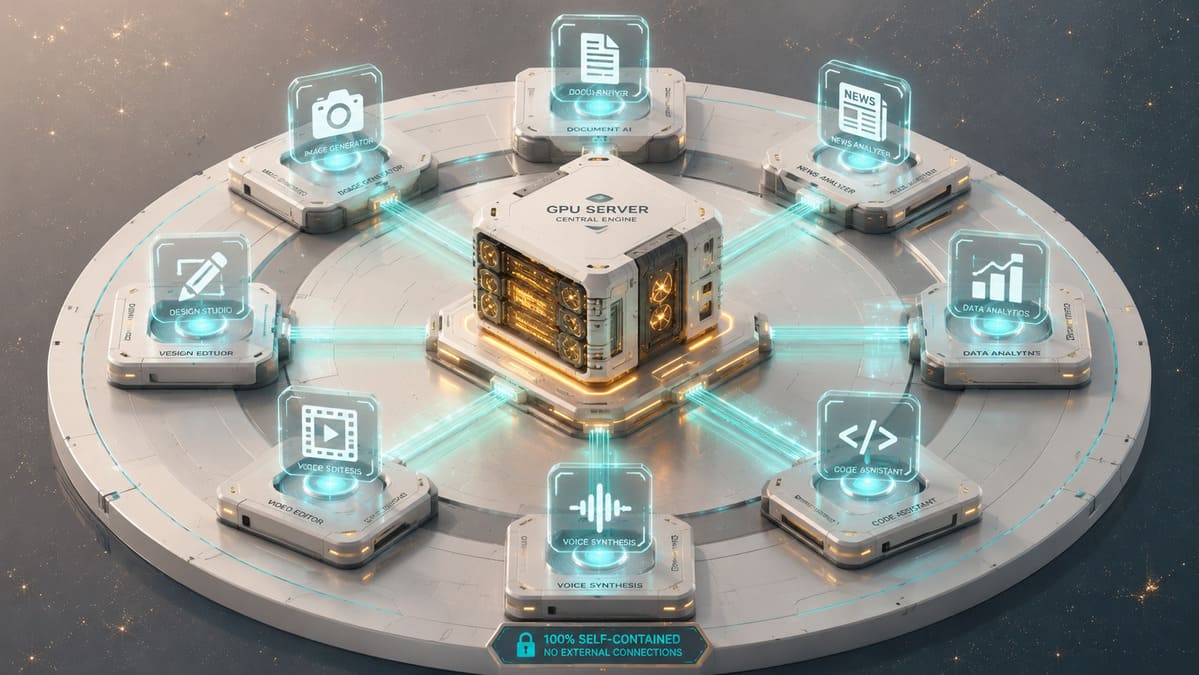
A complete tour of our self-hosted AI infrastructure: 8 applications, 3 ML models, 12+ pipelines. Total monthly cloud API cost: $0. Here's every tool we use.
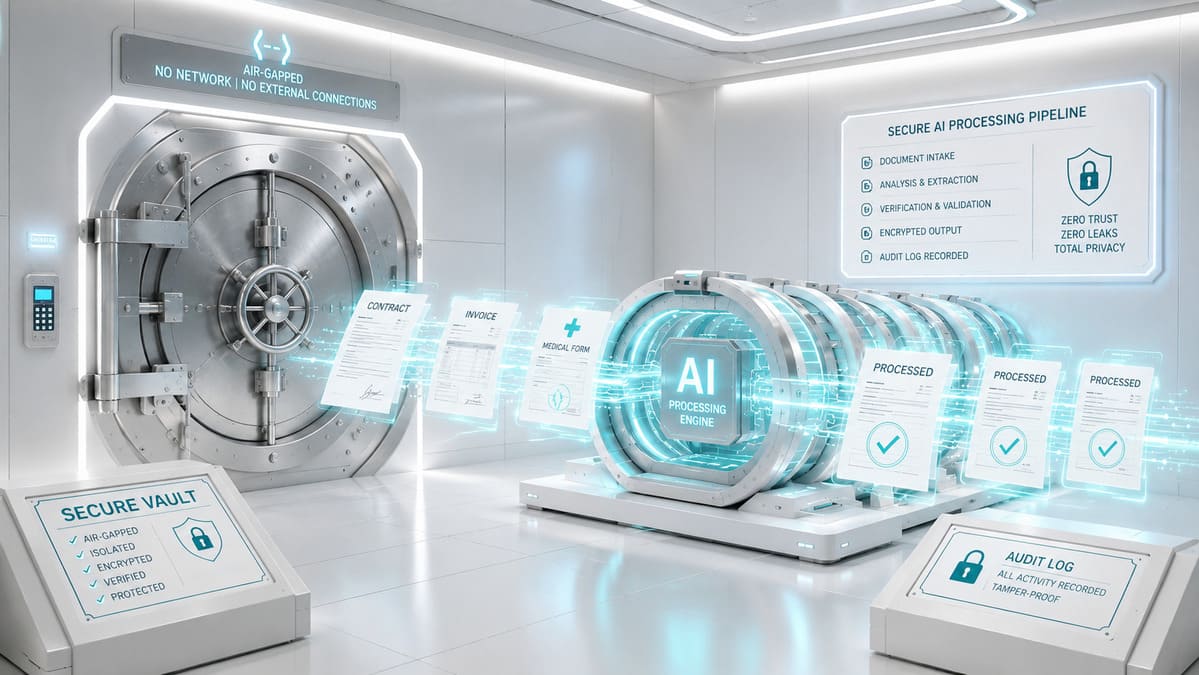
How to build a fully air-gapped system that analyzes contracts, invoices, and medical records using Ollama. No internet connection required, ever.
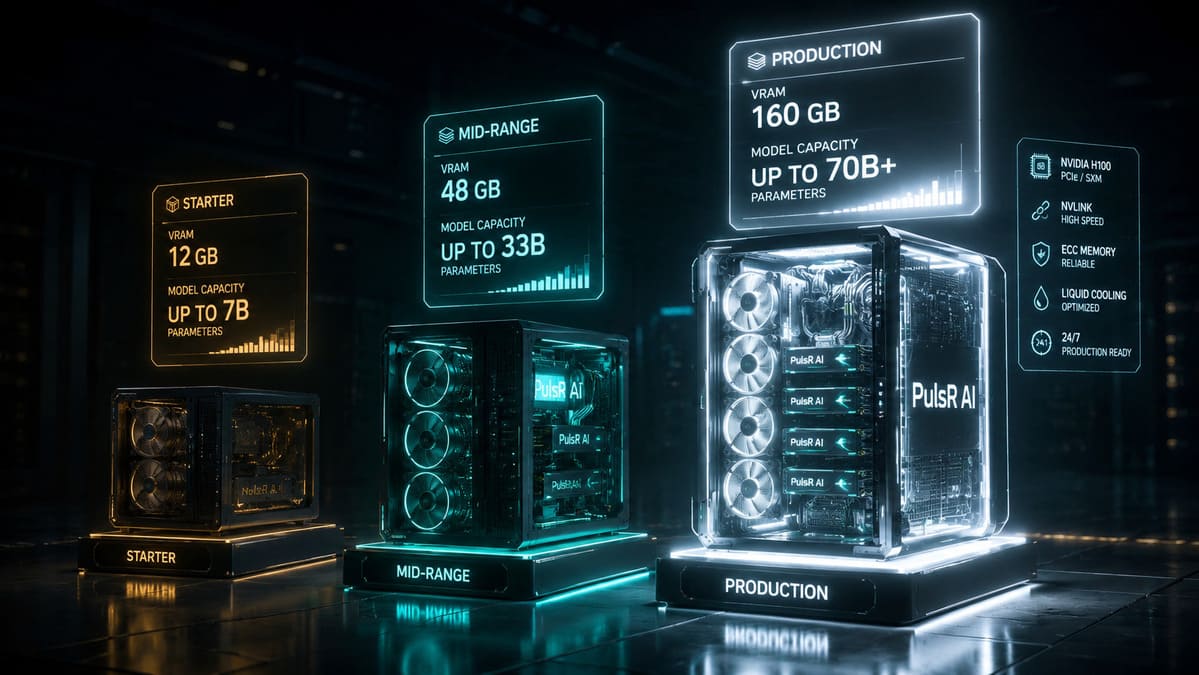
GPU comparison, RAM requirements, storage sizing, and three budget tiers for building your own private AI server. From $1,500 starter to $15,000 production.
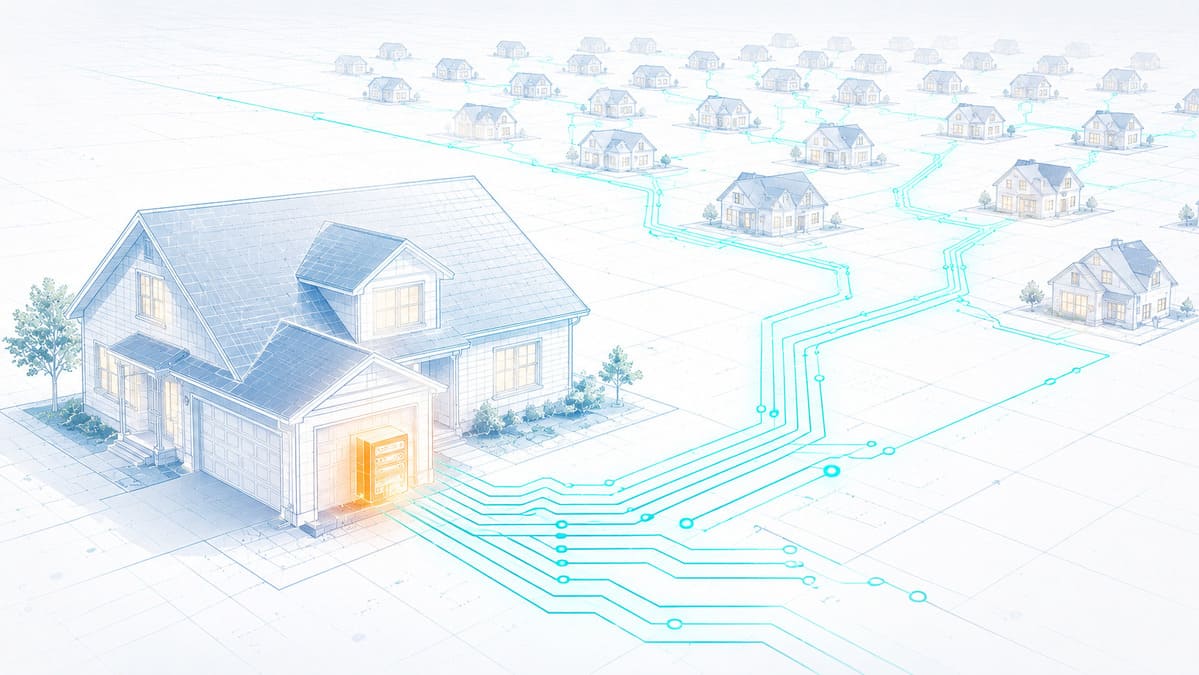
A bold new AI infrastructure idea is emerging: instead of waiting years to build massive data centers, companies want to distribute GPU-powered compute nodes directly into residential homes. NVIDIA, Span, and PulteGroup's XFRA project promises faster deployment, cheaper power access, and a smarter use of the electric grid - but the deeper story is less about "free compute" and more about shifting costs, operational complexity, and grid risk into new places. This article breaks down the real engineering pattern behind XFRA, why distributed edge-style AI infrastructure is technically compelling, and the hidden trade-offs around thermals, reliability, electricity pricing, and long-term utility capacity that most headlines ignore.