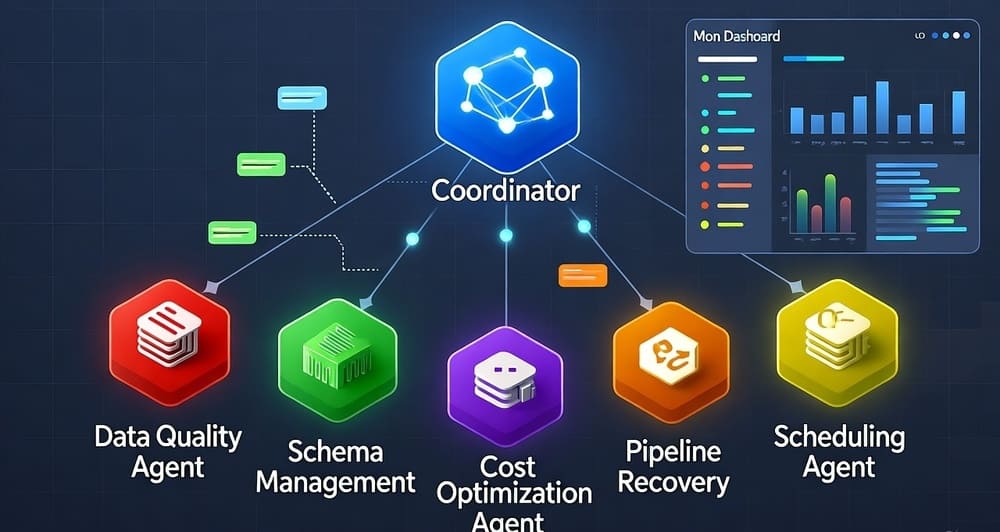
Enterprise data workflows are outgrowing single-agent systems. Organizations process terabytes a day across distributed systems, making decisions about schema changes, data quality, pipeline failures, and resource allocation - and one AI agent can't hold the specialized knowledge each of those domains demands.
Multi-agent orchestration deploys specialized agents that collaborate on complex tasks. Meta runs agents that help engineers query their data warehouse in natural language; Microsoft's Agent Framework lets teams build coordinated agent systems on Azure. These are production systems handling real workloads, not experiments. This article covers how to architect multi-agent systems for data workflows: coordination patterns, communication protocols, and observability when multiple agents work together - including what holds up in production and what does not.
Why single-agent systems fall short
Traditional orchestration tools like Airflow and Prefect execute predefined, deterministic DAGs. Adding intelligence meant hand-coding logic into pipelines. Single AI agents tried to fix this by embedding LLMs into the orchestration layer - interpreting natural-language requests, adjusting schedules by context, responding to failures - but they hit limits quickly.
The specialization problem: a data quality agent needs different knowledge than a cost optimization agent. Training one agent for both degrades each task; the agent becomes a generalist that excels at nothing.
The context problem: enterprise workflows span data warehouses, streaming platforms, object storage, metadata catalogs, and monitoring tools. One agent can't hold connections to all of them while serving requests efficiently.
The scaling problem: as complexity grows, single agents queue requests and become bottlenecks. Adding instances doesn't help if they don't coordinate.
Core architecture patterns
Hierarchical coordination
The most common production pattern uses a coordinator agent that delegates to specialized workers, like a tech lead distributing work. The coordinator receives requests, decides which agents handle them, and manages workflow state; workers focus on their domains.
Meta's data warehouse agents follow this pattern: when an engineer asks about query performance, the coordinator routes to agents for query optimization, schema analysis, and resource usage, then synthesizes their findings into one response.
Give the coordinator a clear decision tree for routing, and use structured LLM outputs for reliable routing decisions rather than parsing free-form text. The coordinator also handles failures - deciding whether to retry, route to a backup, or return a graceful partial response when a worker times out or errors.
Peer-to-peer collaboration
Some workflows benefit from agents communicating directly, without a central coordinator, when they need to negotiate or reach consensus. Consider a pipeline ingesting from multiple sources: one agent monitors source freshness, another validates schema compatibility, a third manages backpressure. They coordinate in real time as conditions change, using message passing to share updates and make collective decisions, which cuts the latency of routing everything through a coordinator.
Use this for workflows where agents must react to each other quickly - real-time processing, dynamic resource allocation, multi-stage validation. The trade-off is debuggability: understanding why agents acted requires tracing message flows across them, so your observability stack has to handle it.
Hub-and-spoke with shared state
This combines both approaches. A central state manager holds shared context while agents communicate directly for time-sensitive coordination. Dagster and Prefect are adding this for AI-enhanced scheduling: agents read shared state about pipeline history, resource availability, and business constraints, coordinate execution through direct communication, and persist state centrally. The shared state becomes the source of truth, preventing the consistency issues that arise when agents keep separate state.
Inter-agent communication protocols
Agents need standardized communication. Ad-hoc message formats turn into integration nightmares as you add agents.
Message structure
Every inter-agent message should include:
- Sender identification - which agent sent it and what role it plays.
- Message type - request, response, notification, or command; each has different handling.
- Payload - the data or instruction, in a structured format like JSON or Protocol Buffers.
- Context - workflow ID, trace ID, and identifiers to correlate messages with tasks.
- Timestamp - when the message was created; critical for debugging timing issues.
Microsoft's Agent Framework implements this through a standardized message envelope, so agents exchange properly formatted messages without knowing each other's internals.
Communication channels
Use existing message brokers for transport rather than building your own:
- Kafka for high-throughput scenarios where agents process event streams - each subscribes to relevant topics and publishes results.
- Redis Streams for lower-latency request-response patterns where agents need quick answers.
- Event-driven architectures on AWS EventBridge or Azure Event Grid, letting one agent's output trigger another's execution without tight coupling.
Choose by latency requirements and existing infrastructure; don't introduce a new broker just for agents if you already run one in production.
Conversation protocols
Agents often need multi-turn interactions - a query-optimization agent might request statistics from a metadata agent, then ask follow-ups. Define protocols specifying initiation (how conversations start and what initial context is required), turn-taking (which agent responds next), and termination (when a complete exchange ends). Without them, conversations stall in loops or deadlock waiting for responses that never come.
Agent specialization strategies
Domain-specific agents
These focus on a technical domain. A schema management agent understands data types, constraints, and evolution; a cost optimization agent knows cloud pricing and utilization patterns. Build them with domain-specific prompts and tools - the schema agent gets tools to query metadata catalogs and analyze table statistics, the cost agent accesses billing APIs and resource monitoring. Fine-tuning a smaller model on a narrow task often beats a large general model: a 7B model fine-tuned on schema management can outperform a 70B general model for that task.
Task-oriented agents
These handle specific workflow tasks regardless of domain - a notification agent sends alerts, a validation agent checks data quality, a scheduler manages timing. They're reusable: the notification agent works the same whether alerting about pipeline failures or quality issues.
Monitoring and governance agents
These observe, analyze, and enforce policy rather than manipulate workflows directly. A lineage agent tracks data flow and maintains governance metadata, a compliance agent checks regulatory requirements, a cost-tracking agent flags anomalies. They run continuously and integrate with your observability stack to correlate agent actions with system metrics.
Observability for multi-agent systems
When multiple agents collaborate, you can't reason from one agent's logs.
Distributed tracing
Implement OpenTelemetry tracing across all agents so each operation becomes a span in a trace that shows the full workflow. When a request triggers five agents, the trace shows the path - coordinator receives, routes to agent A, A queries B, results flow back - exposing latencies and bottlenecks at each step. Track agent-to-agent latency, message queue depths, LLM token usage per agent, decision-making time, and overall completion time.
Agent state visualization
Build dashboards showing which agents are active, what they're working on, and how they communicate. The dashboard should answer: which agents are executing tasks, what conversations are in progress, whether any agent is stuck waiting, and what the message backlog is in each channel.
Decision logging
Agents make autonomous decisions that affect execution. Log every decision with full context - what information the agent had, what options it considered, why it chose an action - so you can reconstruct its reasoning when something goes wrong. Store decision logs separately from application logs; they have different retention and query patterns, and operators asking "why did the system do X" need fast access to decision history.
Governance and security
Agent authentication and authorization
Each agent needs its own identity - no shared credentials. Give every agent a service principal or IAM role with least privilege. The coordinator may need broad orchestration permissions, but a schema-analysis agent doesn't need write access to production databases. Implement agent-to-agent authentication using signed JWTs or mutual TLS so messages provably come from the claimed sender.
Access control policies
Define what each agent can do and access. Enforce policy at three points: the agent level (which tasks it accepts), the resource level (which systems it reaches), and the data level (which specific data it sees). Microsoft's Agent Framework supports declarative policy definitions the platform enforces automatically.
Audit trails
Maintain complete audit logs: agent identity, action taken, resources accessed, decision rationale, timestamp, and outcome, in append-only storage agents can't modify. When regulators ask how data was used, the trail reconstructs the full chain even where agents acted autonomously.
Rate limiting and cost controls
Agents calling LLM APIs can burn budgets fast. Apply rate limits per agent and per workflow. Circuit breakers prevent runaway costs - an agent hitting token limits or too many calls in a window gets throttled or paused while the coordinator handles it gracefully. Track cost by agent to find, say, one agent consuming 80% of your LLM budget through inefficient prompts.
Integration with orchestration platforms
Dagster: agent-enhanced scheduling
Dagster supports context-aware scheduling where agents analyze pipeline history and business constraints to optimize timing - deciding when to run based on data freshness, resource availability, and downstream dependencies rather than cron. The platform exposes APIs for agents to query asset metadata, check partition status, and trigger runs.
Prefect: dynamic workflow modification
Prefect lets agents modify workflows during execution - an agent diagnosing a failure can inject recovery steps or adjust resource allocation without human intervention. This works through Prefect's state management: agents read current state, decide, and use Prefect APIs to modify execution graphs while the platform handles consistency and race conditions.
Flyte: multi-agent task execution
Flyte supports agent-driven task execution where different tasks run on specialized agents - one task uses an SQL-optimization agent, another a data-validation agent. Flyte manages agent lifecycle, provides communication primitives, and handles agents becoming unavailable mid-workflow.
Real-world implementation patterns
Pattern 1: intelligent pipeline recovery
When pipelines fail, a failure-detection agent identifies the problem type and routes to specialized recovery agents: retry logic for transient failures, data repair for quality issues, resource adjustment for capacity problems. The coordinator tracks attempts and escalates to humans when agents can't resolve, cutting mean time to recovery from hours to minutes for common failures.
Pattern 2: natural-language pipeline management
Engineers describe intent in plain English. A language-understanding agent generates a workflow specification, a validation agent checks feasibility, a scheduling agent determines timing, and an execution agent runs the pipeline - replacing hand-written DAG code with described intent.
Pattern 3: cross-system data movement
A source agent extracts using system-specific protocols, a transformation agent applies business rules, a validation agent checks quality, and a destination agent loads with schema mapping. Each specializes in one system or concern and coordinates through the message broker without depending on the others' internals.
Challenges and considerations
Coordination overhead. More agents mean more messages and latency; too much coordination slows workflows. Batch communications where possible, let agents make local decisions for routine operations, and coordinate only for complex scenarios needing multiple perspectives.
Debugging complexity. Root-cause analysis is hard - an individual decision, a communication failure, or a timing issue could be at fault. Invest in distributed tracing and decision logging from day one; they're fundamental, not optional.
Model consistency. Different agents using different LLMs or versions can behave inconsistently. Standardize model versions across agents with similar roles, track them in a model registry, and test multi-agent interactions when updating models.
Prompt drift. Tuning one agent's prompts can change how others interpret its messages. Version-control prompts, test interactions after changes, and keep integration tests that verify multi-agent workflows.
Getting started
Start small rather than building a complete system on day one:
- Phase 1: pick one workflow that benefits from intelligent automation and deploy a single agent for one task. Get comfortable with agent operations, monitoring, and cost management.
- Phase 2: add a second agent that complements the first and implement basic communication. Learn which coordination patterns fit your use cases.
- Phase 3: introduce a coordinator agent and build out observability and governance.
- Phase 4: expand to multiple workflows and more specialized agents once the operational foundations are in place.
Multi-agent orchestration lets enterprises handle complex workflows single agents can't manage, with specialized agents coordinating through standardized protocols. Success hinges on coordination patterns, communication protocols, and observability - you can't debug what you can't see. Build on proven platforms (Dagster, Prefect, Flyte) that are adding agent capabilities rather than building from scratch, and treat agent authentication, authorization, and audit trails as core requirements rather than afterthoughts.
References and further reading
- Microsoft Agent Framework - building multi-agent systems in Azure: https://learn.microsoft.com/en-us/azure/ai-services/agents/
- Dagster - using AI agents with Dagster: https://docs.dagster.io/
- Prefect - building adaptive workflows: https://docs.prefect.io/
- OpenTelemetry - distributed tracing across services: https://opentelemetry.io/docs/
- LangGraph - patterns for building agent systems: https://langchain-ai.github.io/langgraph/



Leave a Comment