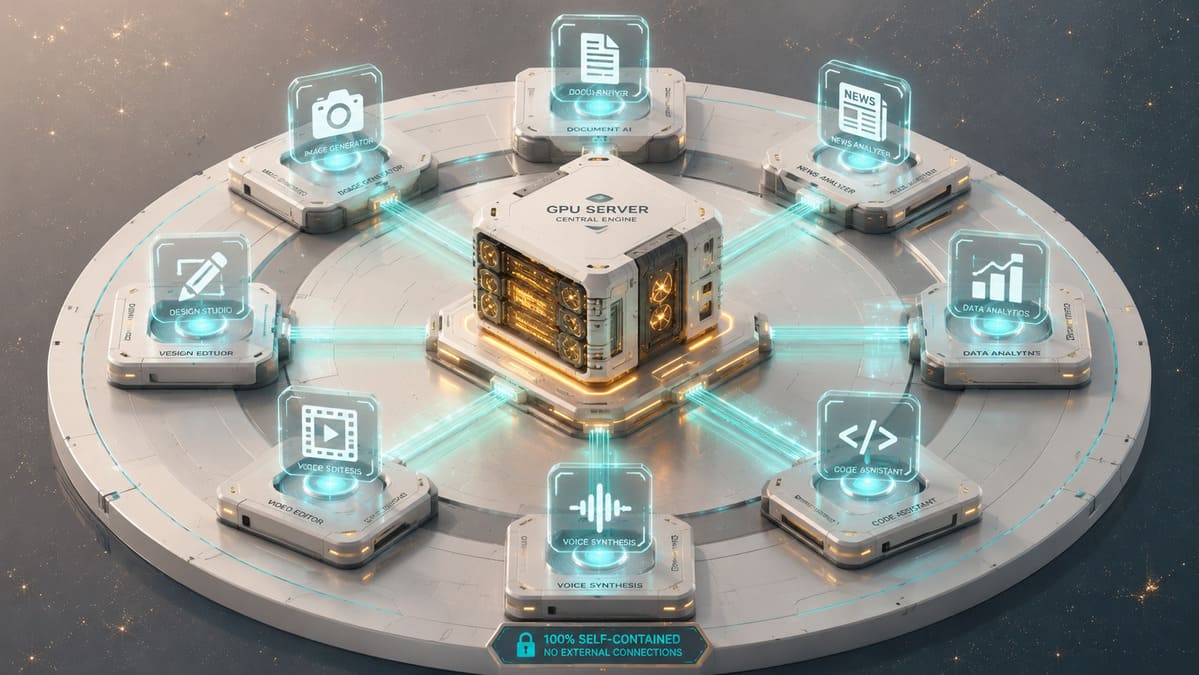
Our monthly cloud AI API bill is $0. Not "almost zero." Not "we optimized it down to $50." Zero dollars. Zero cents. We run eight production AI applications across six websites, processing over 300,000 AI inference requests per month, and not a single token touches OpenAI, Anthropic, Google, or any other cloud AI provider. I am not saying this to brag - I am saying it because eighteen months ago our projected cloud API cost was $2,800 per month and climbing, and the decision to self-host everything was the single best infrastructure decision we made in 2025.
This is a complete, honest tour of our self-hosted AI stack. Every application, every model, every pipeline, every piece of hardware. I am including the parts that work beautifully and the parts that still make me wince. If you are evaluating whether self-hosted AI is viable for your organization, this is the real-world case study that vendor sales decks will never show you.
The Infrastructure Foundation
Before I walk through the applications, here is the hardware and software that powers everything:
Hardware
| Server | Role | Key Specs | Power Draw |
|---|---|---|---|
| GPU Server | AI inference (Ollama) | RTX 4090 24GB, Ryzen 9 7900X, 128GB DDR5, 2TB NVMe | 120-620W |
| Production Server | Apps, databases, pipelines | Xeon E-2388G, 64GB ECC, 4x 2TB NVMe RAID10 | 80-180W |
| Docker Host | Airflow, ClickHouse, Redis | Ryzen 7 5700G, 32GB DDR4, 1TB NVMe | 45-95W |
Software Stack
- Ollama: Model serving. Runs on the GPU server, exposes API on the local network at port 11434.
- PostgreSQL 16 with pgvector: Primary database for all applications. Vector search for RAG pipelines.
- ClickHouse: Analytics database for Pipeline Observatory. Handles time-series pipeline metrics.
- Apache Airflow (Docker): Orchestrates all data pipelines. 12 DAGs running on various schedules.
- Redis: Caching layer for model responses. Saves re-processing identical inputs.
- Nginx: Reverse proxy for all services. TLS termination, rate limiting.
Total monthly infrastructure cost: electricity ~$50, internet $0 (the AI servers do not need internet after initial setup), hardware amortization ~$100/month across a 3-year lifespan. Call it $150/month all-in.
Application 1: LingerieMuseum.com - AI Image Recognition
LingerieMuseum is a product catalog with over 12,000 items. Each product needs accurate tagging: garment type (bra, underwear, bodysuit, robe, etc.), color, material, pattern, brand style. Previously, a data entry specialist spent 20 hours per week manually tagging new products and correcting auto-generated tags from a basic rule-based system.
How It Works
Every new product image is processed through LLaVA 1.6 13B running on our GPU server via Ollama. The pipeline:
- New product images land in an S3-compatible local MinIO bucket
- An Airflow DAG detects new images every 30 minutes
- Each image is sent to Ollama's LLaVA endpoint with a structured prompt
- LLaVA returns a JSON object with category, color, material, pattern, and style tags
- Results are written to PostgreSQL and the product listing is updated
import requests
import base64
import json


def classify_product_image(image_path: str) -> dict:
    """Classify a product image using LLaVA via Ollama."""
    with open(image_path, "rb") as f:
        image_b64 = base64.b64encode(f.read()).decode()

    prompt = """Analyze this product image and return a JSON object with:
- category: the garment type (bra, underwear, bodysuit, robe,
  nightgown, corset, stockings, other)
- colors: list of colors present (use standard color names)
- material_guess: likely material (lace, silk, cotton, satin,
  mesh, leather, polyester)
- pattern: pattern type (solid, floral, striped, polka-dot,
  leopard, geometric, none)
- style: style descriptor (everyday, luxury, sport, vintage,
  bridal, lounge)

Return ONLY the JSON object, no other text."""

    response = requests.post(
        "http://gpu-server:11434/api/generate",
        json={
            "model": "llava:13b-v1.6-q5_K_M",
            "prompt": prompt,
            "images": [image_b64],
            "stream": False,
            "options": {"temperature": 0.1},
        },
        timeout=60,
    )

    result = response.json()["response"]
    return json.loads(result)
Performance
- Volume: ~800 images/week (new products + re-classifications)
- Processing time: 2.1 seconds per image average
- Accuracy: 89% on category (validated against manual tags), 82% on color, 76% on material
- Cloud equivalent cost: Google Vision API at $1.50/1000 images + GPT-4V for classification at ~$0.03/image = ~$128/month
The 76% accuracy on material is the weak point. LLaVA often confuses satin and silk, and struggles to distinguish cotton from polyester in photos. We accept this because the human reviewer catches material misclassifications quickly - it takes 3 seconds to correct a material tag versus 30 seconds to tag from scratch.
Application 2: AllMyQuotes.com - AI Biography Generation
AllMyQuotes is a quotes database with over 170,000 authors. Each author page needs a 150-250 word biography that is accurate, engaging, and SEO-friendly. Writing 170,000 biographies by hand is obviously impossible. Buying them from a content service would cost roughly $0.10-0.25 per bio, or $17,000-42,000.
How It Works
We use Qwen 2.5 7B (the smaller model, intentionally) running on Ollama. For biographies, the smaller model actually performs better than larger ones because the task is straightforward: given a person's name, known quotes, and any available metadata (birth year, profession, nationality), write a concise biography.
def generate_author_bio(
    name: str,
    profession: str = "",
    nationality: str = "",
    birth_year: str = "",
    death_year: str = "",
    notable_quotes: list[str] = None,
) -> str:
    """Generate an author biography using Qwen 2.5."""
    context_parts = [f"Author: {name}"]
    if profession:
        context_parts.append(f"Known as: {profession}")
    if nationality:
        context_parts.append(f"Nationality: {nationality}")
    if birth_year:
        lifespan = f"Born: {birth_year}"
        if death_year:
            lifespan += f", Died: {death_year}"
        context_parts.append(lifespan)
    if notable_quotes:
        quotes_text = "; ".join(f'"{q}"' for q in notable_quotes[:3])
        context_parts.append(f"Notable quotes: {quotes_text}")

    context = "\n".join(context_parts)

    prompt = f"""{context}

Write a 150-250 word biography for this person. Be factual,
engaging, and concise. Focus on their contributions and legacy.
If you are not certain about a fact, omit it rather than guess.
Do not start with the person's name — start with a descriptive
hook. Write in third person."""

    response = requests.post(
        "http://gpu-server:11434/api/generate",
        json={
            "model": "qwen2.5:7b-instruct-q4_K_M",
            "prompt": prompt,
            "stream": False,
            "options": {"temperature": 0.7, "num_ctx": 2048},
        },
        timeout=30,
    )

    return response.json()["response"]
Performance
- Volume: Initial batch of 170,000 bios (took 11 days at ~650/hour), now ~200/week for new authors
- Processing time: 5.5 seconds per bio average
- Quality: ~85% publish-ready without editing. 12% need minor edits. 3% are unusable (usually obscure figures where the model hallucinates facts)
- Cloud equivalent cost: GPT-4-mini at ~$0.003/bio for the initial batch = $510, ongoing ~$2.50/month. This is actually one case where cloud would have been cheaper - but we already had the infrastructure.
Application 3: CelebrityMention.com - Named Entity Recognition
CelebrityMention tracks celebrity mentions across news articles. The NER pipeline identifies person names, organizations, locations, and events in article text. This one does not use Ollama at all - it uses spaCy's transformer-based NER model running on CPU.
How It Works
spaCy's en_core_web_trf model (RoBERTa-based) runs as a Python service on the production server. Articles are ingested via RSS feeds, cleaned, and run through the NER pipeline. Identified entities are linked to our database of 132,000 known celebrities using fuzzy matching.
import spacy
from rapidfuzz import fuzz, process

nlp = spacy.load("en_core_web_trf")

def extract_celebrity_mentions(article_text: str) -> list[dict]:
    """Extract person entities and match against celebrity database."""
    doc = nlp(article_text)

    person_entities = []
    for ent in doc.ents:
        if ent.label_ == "PERSON":
            person_entities.append({
                "name": ent.text,
                "start": ent.start_char,
                "end": ent.end_char,
                "context": article_text[
                    max(0, ent.start_char - 100):ent.end_char + 100
                ],
            })

    # Fuzzy match against known celebrities
    # (celebrity_names loaded from DB at startup)
    for entity in person_entities:
        match = process.extractOne(
            entity["name"],
            celebrity_names,
            scorer=fuzz.token_sort_ratio,
            score_cutoff=85,
        )
        if match:
            entity["matched_celebrity"] = match[0]
            entity["match_score"] = match[1]

    return person_entities
Performance
- Volume: ~2,500 articles/day from 90+ RSS sources
- Processing time: 0.3 seconds per article on CPU
- Accuracy: 94% entity recall, 91% precision on person names. Fuzzy matching catches 97% of known celebrities when they appear.
- Cloud equivalent cost: Google Cloud NLP at $1/1000 text records = $75/month. AWS Comprehend would be similar.
spaCy is honestly the hero of this application. It runs on CPU, it is fast, and the transformer-based model is remarkably accurate. For NER specifically, I would choose spaCy over an LLM every single time - it is purpose-built for the task and 100x faster.
Application 4: FreeDiva.com - Fashion Styling AI
FreeDiva uses Qwen2-VL (vision-language model) to analyze fashion photos and provide styling suggestions. Users upload outfit photos and get feedback on color coordination, style coherence, and accessory suggestions.
Performance
- Volume: ~400 image analyses/week
- Processing time: 3.8 seconds per analysis
- Model: Qwen2-VL 7B via Ollama
- Cloud equivalent cost: GPT-4V at ~$0.04/analysis = ~$70/month
Application 5: Go2Land.com - Resume Analysis
Go2Land is a job matching platform. Candidates upload resumes (PDF), and the system extracts skills, experience level, and role fit using DeepSeek-R1 8B. The reasoning model excels here because resume parsing requires understanding implicit information - a "Senior Software Engineer at Google, 2018-2023" implies specific skill levels and technologies even if they are not listed explicitly.
Performance
- Volume: ~150 resumes/week
- Processing time: 8.2 seconds per resume (including PDF extraction)
- Model: DeepSeek-R1 8B Q4_K_M via Ollama
- Accuracy: 88% skill extraction accuracy, 79% experience level classification
- Cloud equivalent cost: GPT-4 at ~$0.05/resume = ~$32/month
Application 6: News Pipeline - Article Rewriting and Summarization
This is our highest-volume AI application. We pull articles from 90+ news sources via RSS, clean and deduplicate them, and then use DeepSeek to rewrite summaries and extract key topics. The rewritten content powers multiple news aggregation sites.
How It Works
def rewrite_article_summary(
    original_title: str,
    original_text: str,
    target_length: int = 200,
) -> dict:
    """Rewrite an article summary using DeepSeek."""
    prompt = f"""Original headline: {original_title}

Original article (first 2000 chars):
{original_text[:2000]}

Tasks:
1. Write a new headline (different wording, same meaning)
2. Write a {target_length}-word summary capturing the key facts
3. Extract 3-5 topic tags
4. Rate newsworthiness 1-10

Return as JSON with keys: headline, summary, tags, newsworthiness"""

    response = requests.post(
        "http://gpu-server:11434/api/generate",
        json={
            "model": "deepseek-r1:8b-q4_K_M",
            "prompt": prompt,
            "stream": False,
            "options": {"temperature": 0.4, "num_ctx": 4096},
        },
        timeout=45,
    )

    return json.loads(response.json()["response"])
Performance
- Volume: ~1,200 articles/day from 90+ sources
- Processing time: 6.3 seconds per article
- Daily processing window: Runs in 4 batches of 300 articles, ~32 minutes per batch
- Cloud equivalent cost: GPT-4-mini at ~$0.005/article = ~$180/month. This is the application where self-hosting saves the most money.
Application 7: Pipeline Observatory - ML Failure Prediction
The Observatory is our internal data reliability platform. It monitors all data pipelines, detects anomalies in data freshness and volume, and uses an XGBoost model trained on historical pipeline runs to predict failures before they happen.
How It Works
This one is different from the other applications - it does not use LLMs at all. The ML model is a gradient-boosted decision tree trained with scikit-learn and XGBoost on features like: time since last run, historical success rate, day of week, data volume trends, error rate patterns. The model outputs a probability of failure in the next 24 hours for each pipeline.
import xgboost as xgb
import numpy as np

def predict_pipeline_failure(features: dict) -> dict:
    """Predict failure probability for a pipeline run."""
    model = xgb.XGBClassifier()
    model.load_model("/opt/observatory/models/failure_predictor.json")

    feature_vector = np.array([[
        features["hours_since_last_success"],
        features["rolling_7d_success_rate"],
        features["day_of_week"],
        features["hour_of_day"],
        features["avg_duration_ratio"],  # current / historical avg
        features["consecutive_failures"],
        features["data_volume_zscore"],
    ]])

    probability = model.predict_proba(feature_vector)[0][1]

    return {
        "pipeline": features["pipeline_name"],
        "failure_probability": round(float(probability), 3),
        "risk_level": (
            "critical" if probability > 0.8
            else "high" if probability > 0.5
            else "medium" if probability > 0.3
            else "low"
        ),
    }
Performance
- Pipelines monitored: 12 production pipelines
- Prediction accuracy: 87% recall on failures (catches 87% of actual failures), 82% precision
- Inference time: 3ms per prediction (XGBoost is fast)
- Cloud equivalent cost: AWS SageMaker endpoint for a similar model = ~$50/month for the instance alone. But honestly, XGBoost runs on a Raspberry Pi - this is not a cost-driven decision. We self-host because the training data (pipeline metrics) is already local.
Application 8: Laurela - Prediction Analytics
Laurela uses statistical models and lightweight ML for business prediction analytics - sales forecasting, inventory optimization, customer churn prediction. The models are scikit-learn (Random Forest, Gradient Boosting) trained on client data that stays on-premise.
Performance
- Volume: ~50 prediction batches/week
- Processing time: 0.5-2 seconds per batch
- Models: scikit-learn Random Forest, XGBoost
- Cloud equivalent cost: SageMaker inference endpoint ~$75/month
The Full Cost Comparison
Here is the honest accounting. What we actually spend versus what we would spend on cloud APIs:
| Application | Monthly Volume | Self-Hosted Cost | Cloud API Cost |
|---|---|---|---|
| LingerieMuseum (LLaVA) | 3,200 images | $0 (shared GPU) | ~$128 |
| AllMyQuotes (Qwen 2.5) | 800 bios | $0 (shared GPU) | ~$3 |
| CelebrityMention (spaCy) | 75,000 articles | $0 (CPU only) | ~$75 |
| FreeDiva (Qwen2-VL) | 1,600 images | $0 (shared GPU) | ~$70 |
| Go2Land (DeepSeek) | 600 resumes | $0 (shared GPU) | ~$32 |
| News Pipeline (DeepSeek) | 36,000 articles | $0 (shared GPU) | ~$180 |
| Observatory (XGBoost) | ~50,000 predictions | $0 (CPU) | ~$50 |
| Laurela (sklearn) | ~200 batches | $0 (CPU) | ~$75 |
| Category | Self-Hosted Monthly | Cloud Monthly |
|---|---|---|
| AI inference | $0 | $613 |
| Database hosting | $0 (own hardware) | ~$200 (RDS + ClickHouse Cloud) |
| Airflow / orchestration | $0 (Docker) | ~$150 (MWAA or Astronomer) |
| Electricity | $50 | $0 |
| Hardware amortization | $100 | $0 |
| Total | $150/month | ~$963/month |
The savings are real but I want to be honest: $963/month is not going to bankrupt a company. The cloud cost is lower than many people expect because we use smaller, cheaper models for most tasks (GPT-4-mini, not GPT-4). If we were running everything through GPT-4 or Claude, the cloud costs would be $2,800+/month. The real cost advantage of self-hosting kicks in at scale - if our news pipeline grew to 100,000 articles/day, our self-hosted cost stays at $150/month while cloud costs would scale linearly to $500+/month for that pipeline alone.
What Actually Runs on the GPU at Any Given Time
A common question: how do you run 8 applications on one GPU? The answer is that they do not all run simultaneously. Ollama dynamically loads and unloads models based on demand. At any given moment, typically one or two models are loaded in VRAM:
# Typical VRAM usage at 2 PM on a Tuesday
nvidia-smi
# GPU Memory: 18.2 GB / 24 GB used
# Loaded models: qwen2.5:7b (5.1 GB) + llava:13b (9.1 GB)
# KV cache + overhead: ~4 GB

# After 5 minutes of no LLaVA requests, Ollama unloads it
# GPU Memory: 7.3 GB / 24 GB used
# Loaded models: qwen2.5:7b (5.1 GB)

# When a DeepSeek request comes in, it loads automatically
# Load time from NVMe: ~3 seconds for the 8B model
Model switching takes 2-6 seconds depending on model size, and Ollama handles it automatically. The NVMe storage is critical here - loading a 10GB model from SATA SSD would take 18 seconds, which is noticeable in production.
We schedule our heaviest batch jobs (news pipeline, product image processing) during off-peak hours (midnight to 6 AM) to avoid contention with interactive workloads during the day. Airflow makes this trivial:
# Airflow DAG schedule for batch AI workloads
news_pipeline = DAG(
    "news_rewrite_pipeline",
    schedule_interval="0 1,7,13,19 * * *",  # Every 6 hours starting 1 AM
    max_active_tasks=4,  # Limit concurrent Ollama requests
)

product_classification = DAG(
    "product_image_classification",
    schedule_interval="0 2 * * *",  # 2 AM daily
    max_active_tasks=2,  # LLaVA is memory-hungry
)
The Parts That Still Hurt
Self-hosting AI is not all sunshine. Here is what causes us the most pain:
Model updates require manual intervention. When Qwen 2.5 came out, I had to pull the new model, test it against our existing prompts, verify output quality had not regressed, update the model references in 6 different services, and deploy. Cloud APIs update transparently. This manual process takes 2-4 hours per model update.
GPU failures are catastrophic. When our 4090 had a driver crash last October (turned out to be a kernel update that broke NVIDIA drivers), all eight AI applications went down simultaneously. We had no GPU redundancy. Cloud APIs have built-in redundancy. We now keep a spare RTX 3060 that can handle basic workloads as a failover, but it cannot run the 13B vision models. True redundancy means a second 4090, which is another $1,600.
Quality ceiling is real. GPT-4 is simply better than any model we can run locally. For most of our use cases, the quality difference does not matter - a product classification does not need GPT-4-level reasoning. But for the resume analysis on Go2Land, we see a noticeable quality gap. GPT-4 catches nuances in career trajectories that DeepSeek 8B misses. We accept this trade-off but it is a trade-off.
Monitoring is DIY. Cloud AI providers give you dashboards, usage analytics, error tracking. We built all of that ourselves through Pipeline Observatory. It works, but it took time to build and it is another system to maintain.
When Self-Hosting Makes Sense (and When It Does Not)
Based on running this infrastructure for eighteen months, here is my honest framework:
Self-host when:
- You process more than 10,000 AI requests per month (cost crossover point)
- Data privacy is a genuine requirement, not just a nice-to-have
- You have someone on staff who can maintain Linux servers and debug NVIDIA drivers
- Your workloads are predictable enough to right-size hardware
- You are comfortable with models that are good-enough rather than best-in-class
Use cloud APIs when:
- Volume is low (under 5,000 requests/month) - the math does not work for self-hosting
- You need GPT-4/Claude-level quality and cannot compromise
- Your team does not have infrastructure expertise
- Workloads are highly variable (cloud scales, hardware does not)
- You need to ship fast and iterate - cloud APIs are a curl command away
For us, the decision was clear: high volume, predictable workloads, existing infrastructure expertise, and applications where "good enough" model quality is genuinely good enough. Your calculus might be different, and that is fine. The best infrastructure decision is the one that matches your actual constraints, not the one that sounds most impressive on a blog post.
If you want to see how we built this infrastructure or explore whether a similar self-hosted stack would work for your organization, learn more about our team and approach. We are opinionated about self-hosting but pragmatic about when it does not make sense.



Leave a Comment