
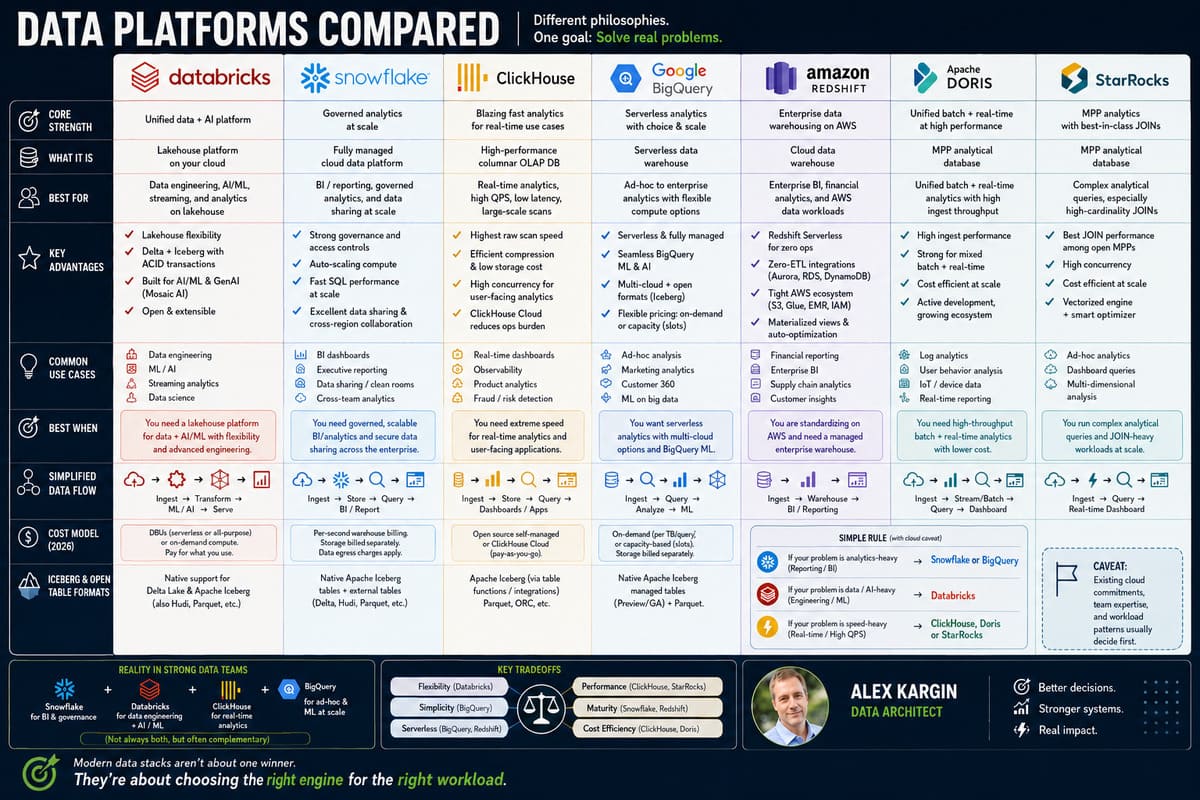
Snowflake and BigQuery built the cloud data warehouse category by hiding the complexity of running analytics infrastructure. A competing pattern has grown up beside them: Delta Lake for reliable, ACID storage on object stores, paired with ClickHouse as the query engine. The trade is the familiar one - a fully-managed warehouse you pay a premium for, versus an open lakehouse stack that is cheaper to run and faster on analytical scans but puts the operational work on your team. The comparison below is about which side of that trade fits your workload, not which one "wins."
Performance and cost, directionally
On analytical query workloads - heavy aggregation and scans over large fact tables - ClickHouse's columnar storage and vectorized execution put it consistently ahead of both managed warehouses, often by several times on the same data. The gap widens for sub-second and high-concurrency cases: ClickHouse degrades gracefully under many concurrent users, while on-demand warehouse pricing and shared compute tiers show larger slowdowns. Snowflake and BigQuery close the gap on mixed, intermittent, or governance-heavy workloads where their managed tuning and serverless scaling matter more than raw latency.
Cost is where the lakehouse stack makes its strongest case. For a steady, high-query workload, a self-managed ClickHouse + Delta Lake deployment typically lands well below an equivalent Snowflake or BigQuery bill, because you pay for infrastructure and storage rather than per-credit or per-byte-scanned compute. The catch is that "self-managed" is a real line item - engineering time to run the cluster - which is exactly what the managed warehouses charge you to avoid.
| Solution | Speed on analytics | Operational burden | Cost shape |
|---|---|---|---|
| ClickHouse + Delta Lake | Fastest on scans/aggregations | High (you run it) or ClickHouse Cloud | Infrastructure + storage; lowest for steady heavy use |
| Snowflake | Solid, versatile | Minimal - fully managed | Per-credit compute; expensive for always-on workloads |
| BigQuery | Serverless, scales well | Minimal - serverless | Per-byte-scanned or slots; unpredictable on wide scans |
Why Delta Lake + ClickHouse fits together
Delta Lake turns a data lake on object storage into an ACID-compliant platform with transactions, schema enforcement, and time travel. The MERGE operation handles upserts cleanly, which is what makes a raw Parquet lake behave like a warehouse:
deltaTable.merge(newData.alias("updates"), "target.id = updates.id") \
  .whenMatchedUpdate(set={"value": "updates.value", "updated_at": "current_timestamp()"}) \
  .whenNotMatchedInsert(values={"id": "updates.id", "value": "updates.value",
                                "created_at": "current_timestamp()"}) \
  .execute()
ClickHouse serves the queries. A MergeTree table partitioned and ordered for your access pattern, with an AggregatingMergeTree materialized view for the hot metrics, gives sub-second dashboards over the same data Delta Lake curates:
CREATE TABLE sales_analytics (
    date Date, customer_id UInt64, product_id UInt64, revenue Float64, quantity UInt32
) ENGINE = MergeTree()
PARTITION BY toYYYYMM(date)
ORDER BY (customer_id, product_id, date);

CREATE MATERIALIZED VIEW customer_metrics_mv
ENGINE = AggregatingMergeTree() PARTITION BY toYYYYMM(date) ORDER BY (customer_id, date)
AS SELECT customer_id, date, sumState(revenue) AS total_revenue, countState() AS txns
FROM sales_analytics GROUP BY customer_id, date;
A typical pipeline lands streaming data (Kafka, Spark Structured Streaming) into Delta tables on S3 partitioned by date, then serves it from a ClickHouse cluster behind Grafana or notebooks. Delta is the durable, governed system of record; ClickHouse is the fast read path.
Keeping the lakehouse fast
Two maintenance habits matter most. On the Delta side, compact small files and Z-order on the columns you filter by, then vacuum old versions so storage doesn't grow unbounded:
deltaTable.optimize().executeZOrderBy("customer_id", "product_category")
deltaTable.vacuum(retentionHours=168)   # keep 7 days of history
On the ClickHouse side, pick the table engine and sort key to match query filters, lean on materialized views for real-time aggregates, and use RBAC plus TLS for access control. Time travel also gives Delta a clean answer to GDPR erasure: DELETE the user's rows, then VACUUM with zero retention to remove them permanently.
When to choose which
Delta Lake + ClickHouse fits high-volume analytical workloads that need sub-second responses, cost-sensitive environments with predictable usage, organizations that want vendor independence and architectural control, and teams with the engineering capacity to run infrastructure (or willingness to use ClickHouse Cloud for the managed middle ground).
Snowflake or BigQuery remains the better call for small-to-medium volumes queried infrequently, teams without dedicated infrastructure engineers, heavily regulated environments that need enterprise support contracts, and anyone who would rather pay more than operate a database. Many organizations run a hybrid: a managed warehouse as the governed central store, with ClickHouse as a fast serving layer for the high-volume, user-facing slices. The honest decision starts with a cost analysis of your current warehouse spend and a look at which query patterns would actually benefit from ClickHouse's speed - then a pilot on a non-critical workload before committing.
Leave a Comment