Neon gives you 100 projects for free, with 1 GB of Postgres storage each
Database storage on the Neon Free plan is now 1 GB per project, up from 0.5 GB. You still get 100 projects, with existing projects getting the new limit automatically.
Database storage on the Neon Free plan is now 1 GB per project, up from 0.5 GB. You still get 100 projects, with existing projects getting the new limit automatically.
Neon AI Gateway now serves embedding models on the same OpenAI-compatible endpoint and with the same credential you already use for chat. Generate vectors, store them in Lakebase Postgres, and query...
ClickHouse Managed Postgres uses direct I/O and stripe-sized reads to keep backups fast while protecting the page cache and query latency.
The opportunity: Personalization as a revenue engineEvery second a shopper spends...
Learn how to monitor a real-time data pipeline with Estuary’s native dashboard, alerts, flowctl, and OpenMetrics API, then extend monitoring with Prometheus to track freshness, throughput, backlog,...
It's simply impossible to not hear about Jev. Seemingly everyone is tinkering with it in some way, from using it to make trading decisions (what could possibly go wrong?) to generating UIs with it...
Rogo on Vercel73,000+ deployments in a single monthAgent-written code shipped to production in 5 minutes6 production AI agents automating work from churn analysis to deal deskZero manual triage...
A Forrester Consulting study finds that enterprises deploying Elastic Observability achieve a 362% ROI, $28.1 million in three-year benefits, and payback in under six months, all while reclaiming...
Anthropic invests $100 million to train 10,000 engineers and tackle the enterprise AI talent gap
Chatham Financial uses Codex and GPT-5.6 to build technology and redesign workflows, cutting trade validation from 30 minutes to under 4.
When a query groups on long, repeated strings, move the strings into a small dimension table with sorted, narrow integer keys. Aggregate on the keys, then join the strings back in at the very end....
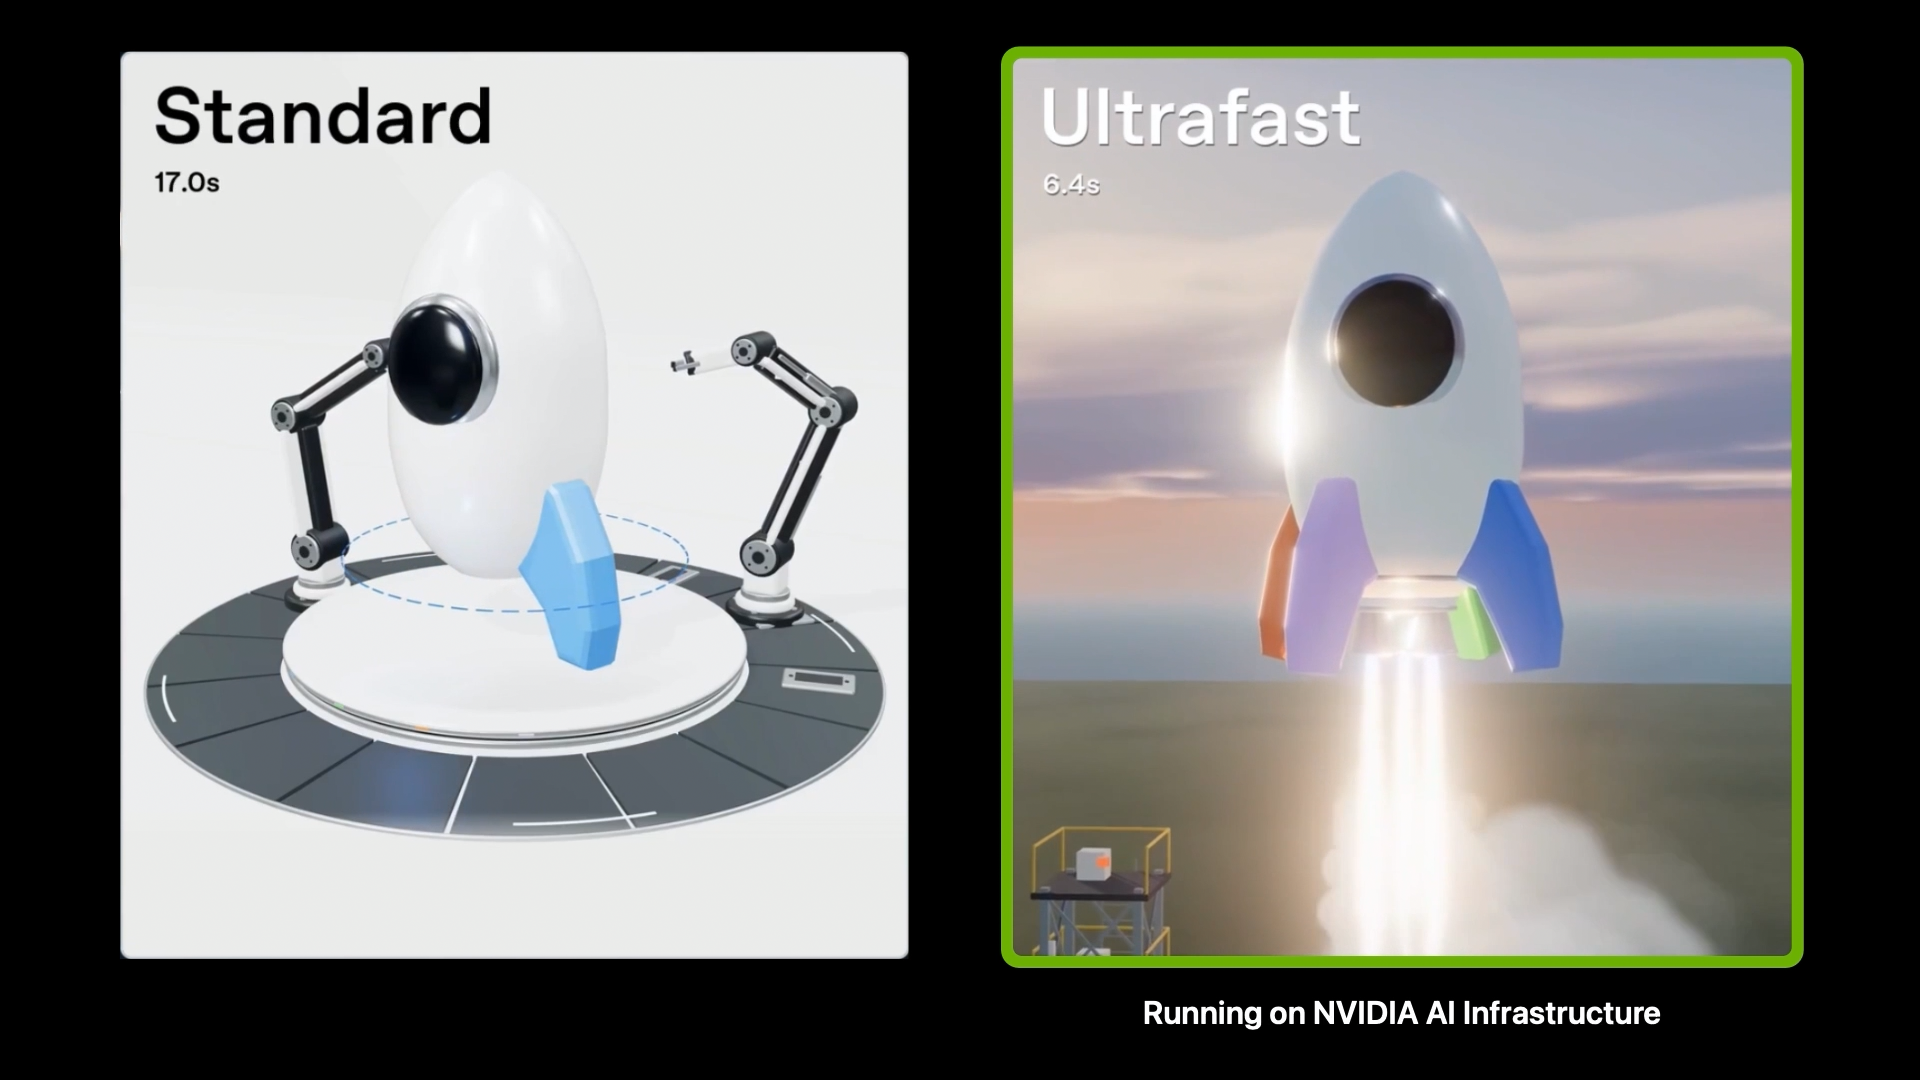
GPT-6 Astra Ultrafast, running on NVIDIA Blackwell GPUs, is available now in the OpenAI API and to eligible ChatGPT Work and Codex users. Accelerated by inference optimizations through OpenAI’s...
A finance team’s job is not simply to report the numbers: it’s to interpret what...
Learn how AWS Professional Services uses a multi-agent framework built on Amazon Bedrock AgentCore to automate enterprise cloud migrations end to end. Purpose-built AI agents handle discovery,...
With Live Data in Apps in Amazon Quick, AI-built apps query your governed Quick Sight datasets in real time instead of static, build-time snapshots. Each query runs as the person viewing the app, so...
In managed OLTP, restores have always been painfully slow and they get slower at...
Learn how to use Amazon S3 Vectors as the persistent memory layer within the NVIDIA NeMo Agent Toolkit (NAT), deployed on Amazon Elastic Kubernetes Service (Amazon EKS). This post shows how NAT's...
Most enterprise AI agents never make it past the pilot stage. The obstacle is rarely …
How we built a model router into Open SWE's harness that cut median cost per coding task by 64% with no measurable drop in quality, and how to build your own.