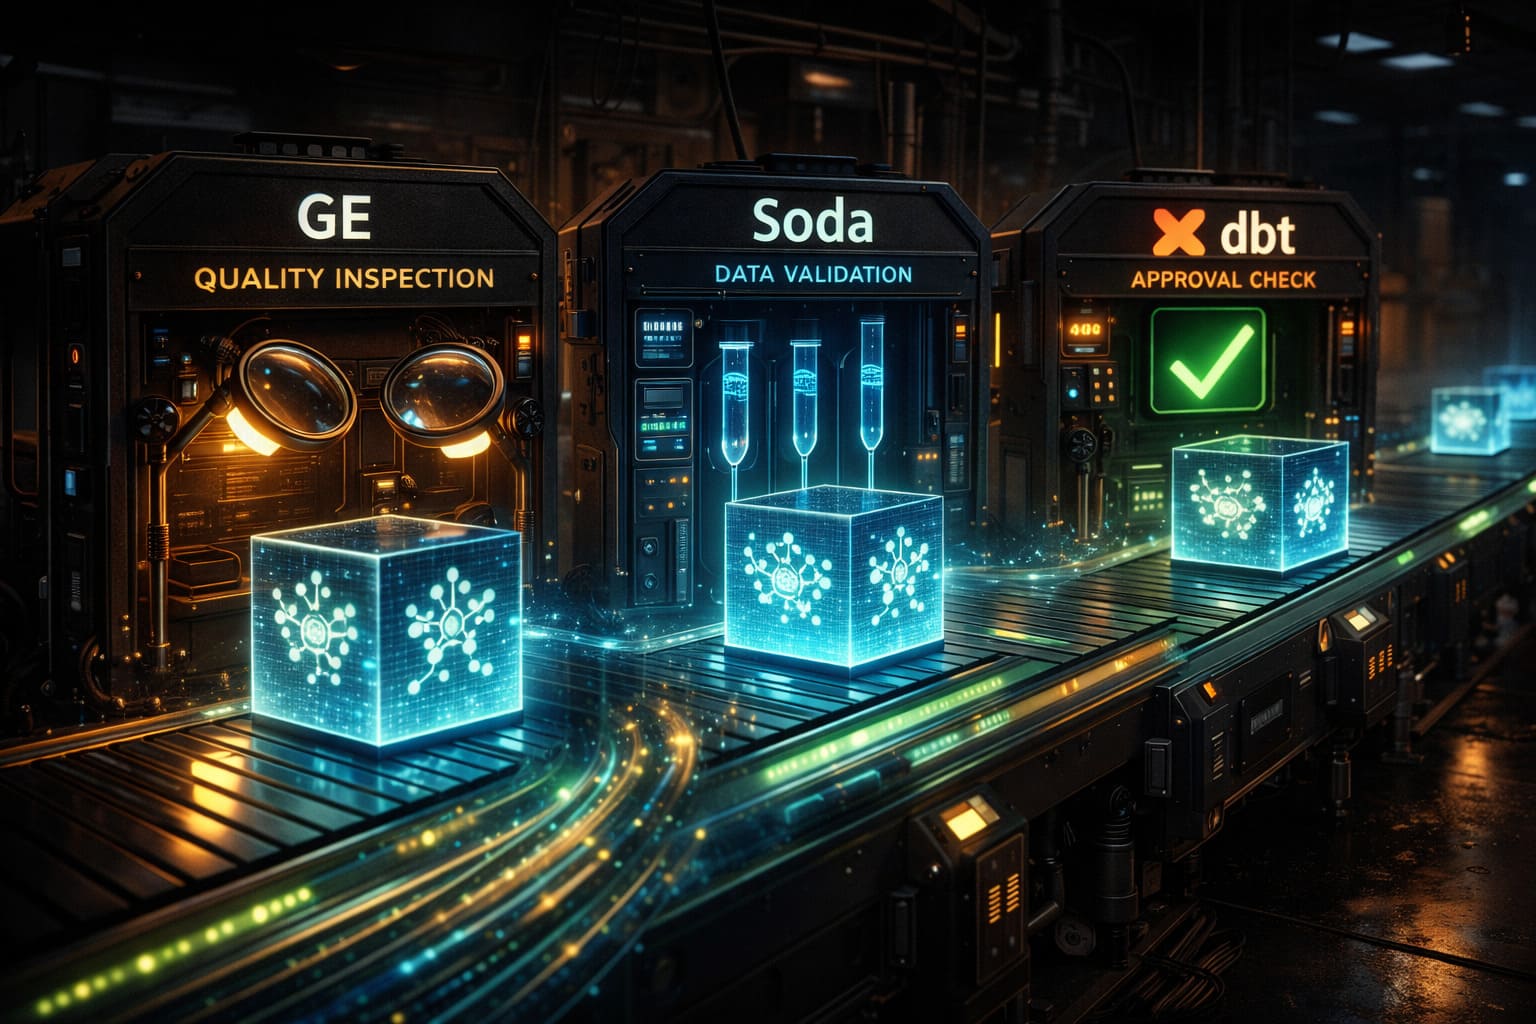
TL;DR: dbt tests are the lowest-friction choice if you already live in dbt. Soda Core gives you the best YAML-driven experience for warehouse-agnostic checks with minimal code. Great Expectations is the heavyweight champion for complex, programmatic validation at scale. Most mature teams end up combining two of the three.
Key Takeaways
- Great Expectations offers the deepest validation library and best data documentation (Data Docs), but the learning curve and setup overhead are real.
- Soda Core is the fastest path to YAML-defined data quality checks with built-in anomaly detection and Slack alerting out of the box.
- dbt tests are unbeatable when your transformations and tests live in the same project, but they only cover what dbt can see.
- Architecture matters more than feature lists. GE is Python-first, Soda is YAML-first, dbt tests are SQL-first.
- At scale, the performance characteristics diverge significantly, especially around full-table scans and incremental validation.
Why Data Quality Testing Is a Solved Problem That Nobody Has Solved
Most production data incidents trace back to one root cause: bad data that nobody caught in time. A partner changes their CSV delimiter. A schema migration drops a NOT NULL constraint. An upstream API starts returning null values in a field that had been populated for three years straight.
A common adoption path looks like this: start with Great Expectations because it has the most mindshare, layer in Soda when a platform team wants something less Pythonic, then notice that half of those checks were already expressible as dbt tests. This comparison draws on running all three in production across different projects, warehouses, and team compositions.
For a team evaluating a data quality framework, or debating whether to migrate from one tool to another, the trade-offs below cover the months of trial and error each option imposes.
What Each Tool Actually Is
Great Expectations
Great Expectations (GE) is a Python library for validating, documenting, and profiling data. You define "Expectations" (individual assertions about your data), group them into "Expectation Suites," run them against "Batches" of data via "Checkpoints," and get results back as structured JSON. The framework also generates "Data Docs," which are static HTML sites showing validation results over time.
GE operates as a standalone validation engine. It connects to your data source directly, whether that is a Pandas DataFrame, a Spark DataFrame, or a SQL database. It does not depend on any orchestrator or transformation tool. That independence is both its greatest strength and the source of most of its complexity.
Soda Core
Soda Core is an open-source data quality tool where you define checks in YAML files called "Soda Checks Language" (SodaCL). You point it at a data source, write your checks in a declarative syntax, and run a scan. Soda also offers Soda Cloud (commercial) for dashboards, alerting, and collaboration, but the core scanning engine is fully open source.
The design philosophy is explicit: keep the configuration human-readable and the integration surface small. You write YAML, you run a CLI command, and you get pass/fail results. No Python class hierarchies, no configuration objects, no context managers.
dbt Tests
dbt tests are assertions you write directly in your dbt project. There are two flavors: schema tests (declared in YAML as properties of your models) and data tests (standalone SQL queries that return failing rows). Since dbt 1.5, custom generic tests and the unit_tests feature have expanded what is possible, but the core idea remains the same: tests are SQL queries that run after your transformations, inside the same project and the same warehouse connection.
dbt tests are not a separate tool. They are a feature of dbt, which means they inherit all of dbt's strengths (version control, documentation, lineage) and all of its constraints (SQL-only, warehouse-bound, tied to your dbt project graph).
The Same Check in All Three Tools
Let's start concrete. Suppose we have an orders table and we want to validate three things: the order_id column has no nulls, the order_total is always positive, and the status column only contains known values. Here is the same logic in each tool.
Great Expectations
import great_expectations as gx

context = gx.get_context()

# Connect to data source
datasource = context.sources.add_or_update_postgres(
    name="warehouse",
    connection_string="postgresql+psycopg2://user:pass@host:5432/analytics"
)
data_asset = datasource.add_table_asset(name="orders", table_name="orders")
batch_request = data_asset.build_batch_request()

# Create expectation suite
suite = context.add_or_update_expectation_suite("orders_quality")

# Define expectations
validator = context.get_validator(
    batch_request=batch_request,
    expectation_suite_name="orders_quality"
)

validator.expect_column_values_to_not_be_null(column="order_id")
validator.expect_column_values_to_be_between(
    column="order_total", min_value=0.01
)
validator.expect_column_values_to_be_in_set(
    column="status",
    value_set=["pending", "confirmed", "shipped", "delivered", "cancelled"]
)

validator.save_expectation_suite(discard_failed_expectations=False)

# Run checkpoint
checkpoint = context.add_or_update_checkpoint(
    name="orders_checkpoint",
    validations=[{
        "batch_request": batch_request,
        "expectation_suite_name": "orders_quality"
    }]
)

result = checkpoint.run()
print(f"Success: {result.success}")
Soda Core
# configuration.yml
data_source warehouse:
  type: postgres
  host: host
  port: 5432
  username: user
  password: ${POSTGRES_PASSWORD}
  database: analytics
  schema: public
# checks/orders.yml
checks for orders:
- missing_count(order_id) = 0:
name: Order ID must not be null
- min(order_total) > 0:
name: Order total must be positive
- invalid_count(status) = 0:
name: Status must be a known value
valid values:
- pending
- confirmed
- shipped
- delivered
- cancelledThen run it:
# Or simply from CLI: soda scan -d warehouse -c configuration.yml checks/orders.yml

from soda.core.scan import Scan

scan = Scan()
scan.set_data_source_name("warehouse")
scan.add_configuration_yaml_file("configuration.yml")
scan.add_sodacl_yaml_file("checks/orders.yml")
scan.execute()

print(f"Has failures: {scan.has_check_failures()}")
dbt Tests
# models/staging/schema.yml
version: 2

models:
  - name: stg_orders
    columns:
      - name: order_id
        tests:
          - not_null
      - name: order_total
        tests:
          - dbt_utils.accepted_range:
              min_value: 0.01
              inclusive: true
      - name: status
        tests:
          - accepted_values:
              values:
                - pending
                - confirmed
                - shipped
                - delivered
                - cancelled
Run with dbt test --select stg_orders. That is it. No connection configuration beyond what is already in your profiles.yml. No Python. No extra dependencies (assuming you have the dbt_utils package installed).
Architecture Differences That Actually Matter
GE's Suite-Based Approach
Great Expectations organizes everything around the concept of a Data Context. Your project directory contains stores for expectations, validation results, data docs configs, and checkpoint definitions. This means GE has opinions about your project layout. The upside is reproducibility: everything is version-controlled and self-documenting. The downside is that the abstraction layers stack up fast. To validate one table, you need to understand Data Sources, Data Assets, Batch Requests, Expectation Suites, Validators, and Checkpoints. Six concepts before you can check if a column has nulls.
GE's V1 release (late 2024) simplified this substantially from the older V0.x API, but it is still the most conceptually heavy of the three tools. The tradeoff is worth it when you have hundreds of tables and want a consistent, programmatic framework that scales across teams.
Soda's YAML-First Design
Soda puts the check definition front and center. The SodaCL language is designed so that a non-engineer can read a check file and understand what is being validated. Configuration is minimal: a data source connection and your check files. There is no project scaffolding, no stores, no multi-layer abstraction. You write YAML, you run a scan, you get results.
This simplicity is genuine. Analytics engineers who have never written a data quality test can read a Soda check file and author their own within 30 minutes. Great Expectations does not offer the same on-ramp.
dbt's Native Integration
dbt tests live inside your dbt project. They share the same connection, the same ref() resolution, the same documentation site, the same CI pipeline. There is zero additional infrastructure. When a test fails, you see it in the same dbt run log as your model builds. The lineage graph shows which models depend on which tests.
The limitation is equally clear: dbt tests can only validate what dbt can query. Raw source data before ingestion, files in object storage, API responses before loading, data in a different warehouse than your dbt project -- none of that is reachable. dbt tests are powerful within their boundary and invisible outside of it.
Setup Complexity: Honest Assessment
| Factor | Great Expectations | Soda Core | dbt Tests |
|---|---|---|---|
| Time to first test | 30-60 minutes | 10-15 minutes | 5 minutes (if you already have dbt) |
| Python required | Yes (heavily) | Yes (minimally, CLI works) | No |
| Config files | great_expectations.yml + multiple stores | configuration.yml + check files | schema.yml (already exists) |
| New concepts to learn | 6+ (Context, Suite, Validator, Checkpoint...) | 2 (Data source, SodaCL syntax) | 1-2 (schema tests, data tests) |
| Dependencies installed | ~80 packages | ~20 packages | 0 (part of dbt) |
| Project scaffolding | Yes (directory structure required) | Minimal (2 YAML files) | None |
A first Great Expectations setup can easily burn an afternoon on Data Context initialization and store configuration. The V1 API improved this, but it remains the most involved setup of the three. Soda Core can be running in production within a single sprint. dbt tests turn on in an existing project with a one-line YAML addition.
CI/CD Integration
All three tools integrate cleanly into CI/CD pipelines, but the ergonomics differ.
Great Expectations in CI
# .github/workflows/data-quality.yml
- name: Run GE checkpoint
  run: |
    pip install 'great_expectations[postgres]'
    python -c "
    import great_expectations as gx
    context = gx.get_context()
    result = context.run_checkpoint('orders_checkpoint')
    if not result.success:
        raise SystemExit(1)
    "
GE gives you structured JSON results, which is great for building custom dashboards or feeding into observability platforms. The Data Docs static site can be deployed to S3 or GCS as a quality report. But you are maintaining Python scripts to wire it all together.
Soda Core in CI
# .github/workflows/data-quality.yml
- name: Run Soda scan
  env:
    POSTGRES_PASSWORD: ${{ secrets.POSTGRES_PASSWORD }}
  run: |
    pip install soda-core-postgres
    soda scan -d warehouse -c configuration.yml checks/
Soda's CLI-first design makes CI integration dead simple. The exit code reflects pass/fail. If you use Soda Cloud, results are pushed automatically. The scan output is human-readable in the CI log without any extra formatting.
dbt Tests in CI
# .github/workflows/data-quality.yml
- name: Run dbt tests
  run: |
    dbt deps
    dbt build --select tag:quality_critical
    # or: dbt test --select stg_orders
A CI pipeline already running dbt build runs its tests automatically. The dbt build command interleaves model runs and tests, so a failing test halts downstream models. This is the tightest feedback loop of the three: build and validate in a single command.
Alerting and Notifications
When a data quality check fails at 3 AM, how do you find out?
Great Expectations has an Action system where you attach actions to checkpoints. Out of the box, it provides Slack, email, PagerDuty, and OpsGenie integrations, plus custom actions in Python. The configuration is verbose but flexible. A common workaround is a wrapper script that parses GE results and sends formatted Slack messages, because the built-in Slack action's formatting is often not detailed enough.
Soda Core with Soda Cloud gives you built-in Slack and webhook integrations with no code. The open-source Soda Core alone does not have alerting, so you either use Soda Cloud or build your own notification layer around the scan results - a roughly 40-line Python wrapper that parses the scan output and posts to Slack is enough. Not hard, but worth knowing it is not batteries-included in the OSS version.
dbt tests rely on whatever alerting your orchestrator provides. dbt via Airflow inherits Airflow's alerting; dbt Cloud provides its built-in Slack and email notifications. The Elementary dbt package belongs in this list: it adds anomaly detection, test result history, and a Slack alerting bot specifically for dbt tests, and it fills the gap well.
Custom Checks and Extensibility
Great Expectations: Custom Expectations
from great_expectations.expectations import ExpectationConfiguration
from great_expectations.core import ExpectationValidationResult
from great_expectations.expectations.expectation import ColumnAggregateExpectation


class ExpectColumnValuesFreshnessWithinHours(ColumnAggregateExpectation):
    """Expect the most recent timestamp in a column to be within N hours of now."""

    metric_dependencies = ("column.max",)
    success_keys = ("max_hours",)

    default_kwarg_values = {"max_hours": 24}

    def _validate(self, metrics, runtime_configuration, execution_engine):
        column_max = metrics["column.max"]
        max_hours = self.configuration.kwargs.get("max_hours", 24)
        from datetime import datetime, timedelta
        threshold = datetime.utcnow() - timedelta(hours=max_hours)
        success = column_max >= threshold
        return ExpectationValidationResult(
            success=success,
            result={
                "observed_value": str(column_max),
                "threshold": str(threshold)
            }
        )
GE's custom expectation system is powerful but requires understanding the metric/validation architecture. You are writing Python classes with specific method signatures and metric dependencies. For a team of Python engineers, this is fine. For a mixed team with SQL-focused analysts, it is a barrier.
Soda Core: Custom SQL Checks
# Custom freshness check in SodaCL
checks for orders:
  - freshness(updated_at) < 24h:
      name: Orders table must be updated within 24 hours

  # Arbitrary SQL for anything SodaCL doesn't cover
  - failed rows:
      name: Revenue must match line items
      fail query: |
        SELECT o.order_id
        FROM orders o
        JOIN (
          SELECT order_id, SUM(quantity * unit_price) as calc_total
          FROM line_items GROUP BY order_id
        ) li ON o.order_id = li.order_id
        WHERE ABS(o.order_total - li.calc_total) > 0.01
Soda's escape hatch is the failed rows check with a raw SQL query. If SodaCL's built-in checks do not cover a case, you write SQL. The freshness check shown above is built into SodaCL natively. For most data quality scenarios, dropping down to custom SQL is rarely necessary.
dbt Tests: Custom Generic Tests
-- tests/generic/test_freshness_within_hours.sql
{% test freshness_within_hours(model, column_name, max_hours=24) %}

SELECT {{ column_name }}
FROM {{ model }}
WHERE {{ column_name }} = (SELECT MAX({{ column_name }}) FROM {{ model }})
  AND {{ column_name }} < {{ dbt.dateadd("hour", -max_hours, dbt.current_timestamp()) }}

{% endtest %}
# schema.yml
models:
- name: stg_orders
columns:
- name: updated_at
tests:
- freshness_within_hours:
max_hours: 24dbt custom generic tests are Jinja-templated SQL. For anyone comfortable with dbt's Jinja syntax, writing them is fast. The test returns rows that fail the assertion. Zero rows means the test passes. It is elegant in its simplicity but limited to what SQL can express.
Performance at Scale
This is where the tools diverge sharply. The numbers below come from running all three against a 2-billion-row fact table in Snowflake.
| Scenario | Great Expectations | Soda Core | dbt Tests |
|---|---|---|---|
| Not-null check (single column) | 12s | 11s | 10s |
| 10 column checks, same table | 14s (batched) | 45s (sequential queries) | 38s (parallel threads) |
| Uniqueness on high-cardinality column | 28s | 25s | 24s |
| Full suite: 50 checks across 20 tables | 3m 10s | 4m 40s | 2m 50s (8 threads) |
| Incremental (only new partitions) | Native support | Filter syntax | Requires custom macro |
The single-check performance is nearly identical because all three tools push the computation down to the warehouse. The difference shows up in how they batch or parallelize multiple checks.
Great Expectations batches multiple expectations against the same table into fewer queries, which is a meaningful optimization when you have 10+ checks per table. Soda Core runs each check as a separate query by default, though Soda Cloud offers scan optimization. dbt tests run in parallel threads, and the thread count is configurable in profiles.yml.
For incremental validation (only checking recently loaded data), GE has the cleanest support via batch filters on the Data Asset. Soda adds a filter clause to a check. dbt either tests only the incremental model's latest run or uses a custom macro that filters the test query. None of these approaches is difficult, but GE's is the most first-class.
Comprehensive Feature Comparison
| Feature | Great Expectations | Soda Core | dbt Tests |
|---|---|---|---|
| Primary language | Python | YAML (SodaCL) | SQL + YAML |
| Learning curve | Steep | Gentle | Minimal (if you know dbt) |
| Built-in checks | 300+ | ~50 | ~10 (+ dbt_utils, dbt_expectations) |
| Custom checks | Python classes | Raw SQL in YAML | Jinja SQL macros |
| Data profiling | Yes (built-in) | Yes (discover + profile) | No (use dbt-profiler package) |
| Anomaly detection | Via contrib expectations | Built-in (anomaly checks) | Via Elementary package |
| Documentation site | Data Docs (excellent) | Soda Cloud only | dbt Docs (lineage included) |
| Pre-ingestion validation | Yes (Pandas, Spark, files) | Yes (Spark, Pandas) | No (warehouse only) |
| Multi-warehouse | Yes | Yes | Limited (one target per run) |
| Orchestrator agnostic | Yes | Yes | Tied to dbt execution |
| Commercial offering | GX Cloud | Soda Cloud | dbt Cloud |
| License | Apache 2.0 | Apache 2.0 | Apache 2.0 |
When to Combine Tools
These tools are not mutually exclusive. The teams with the most robust data quality practices tend to use a combination.
The pattern that tends to hold up:
- dbt tests for transformation correctness. Every staging and mart model gets
not_null,unique, andaccepted_valuestests on key columns. These run as part ofdbt buildand catch issues before data reaches consumers. Cost: nearly zero, since dbt is already running. - Soda Core for source freshness and cross-system checks. Soda scans run against raw source tables to catch ingestion failures and schema drift before dbt even starts. Soda's freshness checks and anomaly detection work well here because they do not depend on dbt's execution context.
- Great Expectations for complex validation in Python pipelines. ML feature pipelines that transform data in Pandas and Spark before writing to a feature store can have GE validate the DataFrames in-memory at each stage. This is something neither Soda nor dbt can do natively.
The cost of running multiple tools is real: more config files, more CI steps, more things to maintain. But the coverage gap of using only one tool is worse. Maintaining three YAML files beats debugging a silent data quality regression that reached a production dashboard.
Decision Framework
For a team starting from scratch, the choice comes down to where the data lives and what the team is comfortable writing:
Choose dbt tests if:
- You already use dbt for transformations
- Your team is SQL-first and does not want to write Python
- Your data quality concerns are primarily about transformation correctness
- You want the tightest possible integration between transforms and tests
Choose Soda Core if:
- You need to validate data across multiple warehouses or data sources
- Your team prefers declarative YAML over Python or SQL
- You want built-in anomaly detection without extra packages
- You need to validate source data before it enters your transformation layer
- You are a small team and need the fastest path to production data quality checks
Choose Great Expectations if:
- You need to validate data in Python pipelines (Pandas, Spark DataFrames)
- You have 300+ expectations to maintain and need programmatic suite management
- You want the richest set of built-in validators without writing SQL
- Data documentation (Data Docs) is a priority for compliance or governance
- Your team has strong Python skills and does not mind the setup investment
A Sensible Adoption Order
Starting over, the order that minimizes friction is dbt tests from day one - not because they are the most powerful, but because the friction is near zero for a team already using dbt. Add Soda Core next for source monitoring and freshness checks. Bring in Great Expectations only when a specific use case requires in-memory DataFrame validation or programmatic suite generation.
The common mistake is starting with Great Expectations because it has the most features, then getting bogged down in setup and configuration before a single test runs in production. Start simple. Ship something. Expand tooling when you hit the limits of what you have, not before.
Data quality testing comes down to one thing: catching bad data before stakeholders do. Any of these three tools gets you there. The best choice is the one a team will actually adopt and maintain. A dbt project with 200 simple schema tests running on every merge beats a Great Expectations deployment with 50 sophisticated expectations that nobody has updated in six months.
Ship the tests. Fix the ones that are too noisy. Add more when things break.
Leave a Comment