The problem
Data already sits in Iceberg or Hudi. Analysts want BI-speed queries, engineers want zero copy, and security wants private networking. VeloDB (a managed, enterprise distribution of Apache Doris) queries those lake tables directly - with sub-second interactivity - without rebuilding pipelines. Warehouse-like speed over open tables.
What VeloDB is, and why it's fast
VeloDB is a real-time OLAP database built on Apache Doris. Doris has a mature lakehouse path with External Catalogs, vectorized execution, and optimizations for Iceberg/Hudi - including time travel, delete-file handling, incremental read, cross-catalog joins, and write-back to Iceberg. VeloDB ships those capabilities with cloud management and BYOC networking.
The key ingredients:
- Multi-Catalog to attach Iceberg/Hudi once and auto-sync metadata.
- Iceberg engine with V1/V2 support, position/equality deletes, system tables, branches/tags.
- Hudi COW/MOR snapshot and incremental queries plus time travel.
- Data Cache (local NVMe) and Metadata Cache to avoid re-listing remote files and stabilize SLAs.
- Private connectivity for BYOC with AWS PrivateLink-style endpoints.
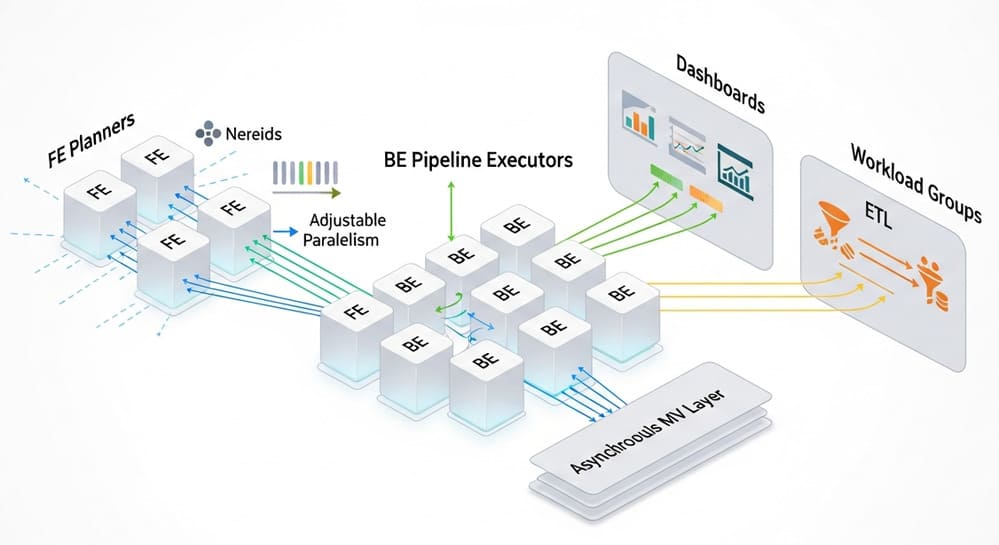
Architecture at a glance
Data path:
- Client (JDBC/MySQL protocol) → VeloDB.
- VeloDB uses the catalog to resolve table metadata (REST/HMS/Glue).
- Files read from object storage (S3/GCS/HDFS). Hot blocks stay in Data Cache on BE nodes.
- Vectorized execution, partition and file pruning, delete-file handling.
Quick start: wire Iceberg and Hudi into VeloDB
1) Create an Iceberg catalog (REST / Unity Catalog, Glue, HMS, Hadoop)
REST (Unity Catalog) example:
CREATE CATALOG dbx_unity_catalog PROPERTIES (
  "type" = "iceberg",
  "iceberg.catalog.type" = "rest",
  "uri" = "https://<dbc>.cloud.databricks.com/api/2.1/unity-catalog/iceberg-rest/",
  "iceberg.rest.security.type" = "oauth2",
  "iceberg.rest.oauth2.token" = "<token>",
  "iceberg.rest.vended-credentials-enabled" = "true",
  "warehouse" = "my-unity-catalog"
);
Then:
USE dbx_unity_catalog.`default`;
SELECT * FROM iceberg_table;
OAuth2 client credentials and static S3 credentials are also supported when not using vended creds. Hadoop / HMS / Glue options work as well; pick the one matching your metastore.
2) Create a Hudi catalog (via Hive Metastore)
CREATE CATALOG hudi PROPERTIES (
  "type" = "hms",
  "hive.metastore.uris" = "thrift://hive-metastore:9083",
  "s3.endpoint" = "http://minio:9000",
  "s3.access_key" = "minio",
  "s3.secret_key" = "minio123",
  "s3.region" = "us-east-1",
  "use_path_style" = "true"
);
REFRESH CATALOG hudi;
Query both COW and MOR tables and use time travel or incremental read when needed.
3) Cross-catalog joins (ZeroETL)
After attaching catalogs, you can join across them - e.g., a Hudi fact to an Iceberg dimension:
SELECT f.order_id, d.category, f.amount
FROM hudi.retail.fact_orders f
JOIN iceberg.dim.dim_product d
  ON f.product_id = d.product_id
WHERE f.order_ts >= NOW() - INTERVAL 1 DAY;
Cross-catalog queries are a first-class Doris feature.
Create and write Iceberg from VeloDB
Create an Iceberg catalog and table, then insert and query:
-- Catalog (REST example for demo)
CREATE CATALOG iceberg PROPERTIES (
  "type" = "iceberg",
  "iceberg.catalog.type" = "rest",
  "warehouse" = "s3://warehouse/",
  "uri" = "http://rest:8181",
  "s3.access_key" = "admin",
  "s3.secret_key" = "password",
  "s3.endpoint" = "http://minio:9000"
);

-- Switch and create table with partition transforms
SWITCH iceberg;
CREATE DATABASE nyc;
CREATE TABLE nyc.taxis (
  vendor_id BIGINT,
  trip_id BIGINT,
  trip_distance FLOAT,
  fare_amount DOUBLE,
  store_and_fwd_flag STRING,
  ts DATETIME
)
PARTITION BY LIST (vendor_id, DAY(ts)) ()
PROPERTIES ("compression-codec"="zstd","write-format"="parquet");

INSERT INTO nyc.taxis VALUES
(1,1000371,1.8,15.32,'N','2024-01-01 09:15:23');

-- Query current snapshot
SELECT * FROM nyc.taxis;
These patterns - CREATE CATALOG, SWITCH, partition transforms, INSERT, and snapshot/time-travel queries - are built in.
Performance tuning for interactive lake queries
1) Turn on Data Cache (hot blocks on NVMe)
- Configure BE
file_cache_pathwith enough space. - Enable at session/global level:
SET enable_file_cache = true;Use for hot time windows (today/last N days). Monitor hit rates in the FE Profile and thefile_cache_statisticssystem table.
2) Right-size Metadata Cache
- Controls database/table lists, schemas, partitions, and file lists.
- Tune eviction/refresh to balance freshness vs. latency (
external_cache_*params).
3) Prune early, prune often
- Use partition transforms (
day(ts),bucket,truncate) to minimize scanned files. - Doris maps Iceberg transforms and supports delete-file semantics, so filters matter.
4) Elastic compute
- Separate compute scales independently; attach catalogs once and scale for peak hours.
5) Secure and stable connectivity
- In BYOC, set private endpoints to the VeloDB Cloud control plane (no public Internet).
When to pick Iceberg vs. Hudi (for query serving)
| Scenario (common in BI/ops) | Prefer Iceberg | Prefer Hudi |
|---|---|---|
| Large batch analytics, schema evolution, multi-engine sharing | ✅ | |
| Real-time upserts with incremental pull for near-real-time dashboards | ✅ | |
| Time travel over stable snapshots | ✅ | ✅ |
| Merge-On-Read (row-level freshness with compacting later) | ✅ |
Both work well through VeloDB: Iceberg brings rich snapshot/branching/system tables, while Hudi shines for incremental ingestion and MOR/COW table types. VeloDB's query engines support both natively.
Best practices and pitfalls
Do this:
- Start with catalog-linked access; don't copy data unless you must.
- Partition on time plus a low-cardinality dimension; add bucket for high-cardinality joins.
- Enable Data Cache on NVMe for the last N days; watch cache hit rate.
- Set sane metadata refresh windows to keep schemas/partitions fresh without hammering HMS/REST.
- Use cross-catalog joins to enrich lake facts with JDBC/operational dims without ETL.
Avoid this:
- Tiny Parquet files (death by file-listing). Compact in your lake tool; Doris caches metadata, but physics wins.
- Over-wide MOR queries with no filters; add predicates and read only needed columns.
- Public networking for BYOC; configure a private endpoint.
Summary
If your data already lives in Iceberg or Hudi, VeloDB queries it at warehouse speed without duplicating tables. Attach catalogs, flip on data/metadata caches, and serve BI and real-time analytics straight from the lake. A good first pass: attach one catalog (REST/HMS/Glue), enable Data Cache, run a cross-catalog join, and measure p95 latency.
References
- VeloDB docs: product overview; Iceberg and Hudi best practices; catalogs and versions; BYOC private endpoints.
- Apache Doris docs: Iceberg and Hudi integration, Multi-Catalog/Catalog Overview, Data/Metadata Cache, Unity Catalog REST integration, and example SQL.
Leave a Comment