What this covers
Clickstream or CDC events pile up in Kafka, BI wants near-real-time dashboards, and there's no tolerance for duplicates or gaps. The pipeline needs to keep up under bursty traffic, survive restarts without re-ingesting old data, tolerate schema changes without constant babysitting, and prove it met its SLA. Apache Doris Routine Load fills that slot: continuous Kafka → SQL table ingestion with exactly-once semantics, low latency, and simple operations.
How Routine Load achieves exactly-once
Kafka topic/partitions
   └─> Routine Load job
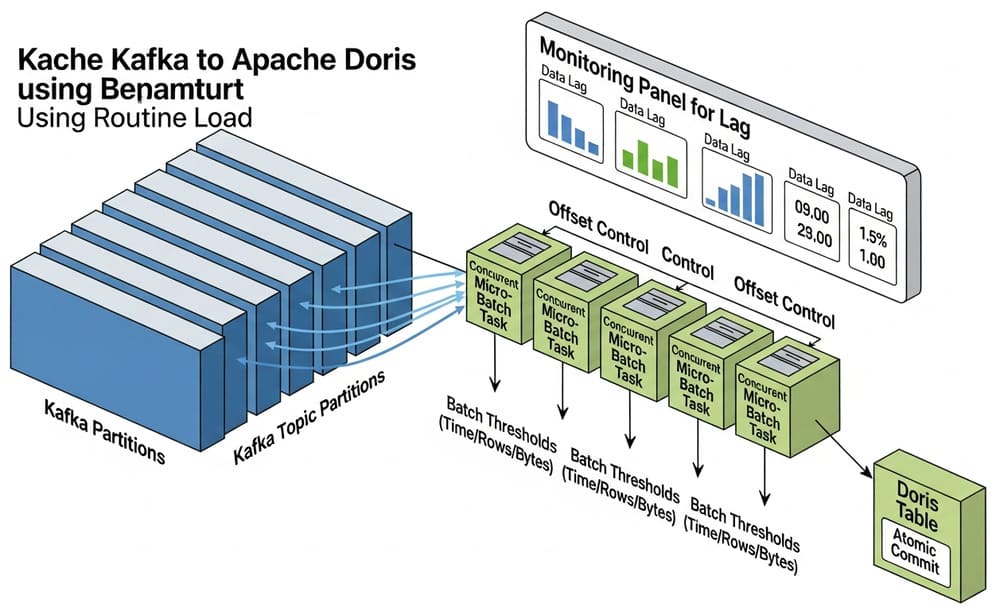
         └─> N concurrent tasks (micro-batches)
               ├─ consume from assigned partitions
               ├─ transform/validate
               └─ commit as a single Doris transaction
- Doris runs the job continuously, splitting it into micro-batch tasks that each map to a transaction. Batches close on time/row/byte thresholds or when EOF is reached.
- Exactly-once is enforced by persisting consumption progress plus commit validation. Even with retries or brief double scheduling, duplicate commits are rejected.
- Jobs auto-recover after transient issues; a manual
PAUSEdisables auto-resume.
Offsets you can reason about
Routine Load lets you control where consumption starts and how to adjust it later:
| What you need | How to do it |
|---|---|
| Start from beginning/end or a specific timestamp | Set default offsets when creating the job (e.g., kafka_default_offsets = '2025-11-20 10:00:00' or OFFSET_BEGINNING). |
| Pin to exact partition offsets | Use kafka_offsets (and optionally kafka_partitions) via ALTER ROUTINE LOAD. Good for surgical replays. |
| Inspect progress & lag per partition | SHOW ROUTINE LOAD (job-level) and SHOW ROUTINE LOAD TASK (subtask-level) expose consumed offsets and lag. |
| Pause, resume, or stop | PAUSE/RESUME/STOP ROUTINE LOAD - resume picks up from the last committed offset; stop is final. |
If a job is paused too long and Kafka retention expires, you'll see "offset out of range." Fix it by resetting offsets to a valid point or recreating the job.
Handling schema drift
Real streams change. Doris gives two layers of control.
1. Loader-level tolerance and mapping. Use Routine Load properties (at create time or via ALTER) to adapt without code redeploys:
- JSON extraction:
format='json',jsonpaths,json_root,strip_outer_array. - Type/format tolerance:
strict_mode(off to coerce where possible),num_as_string,fuzzy_parse. - Partial updates:
partial_columns=truefor UNIQUE KEY + Merge-on-Write tables when not all columns are present.
2. Table-level evolution. Add or modify columns with a schema change (lightweight vs. heavyweight). Use this when the model itself evolves.
Backpressure
Throttle or push throughput by tuning batching and concurrency:
- Batch boundaries (end a micro-batch when any threshold hits):
max_batch_interval(sec),max_batch_rows,max_batch_size(bytes). Lower the interval for latency, raise size/rows for throughput. - Parallelism:
desired_concurrent_number≈ tasks, upper-bounded by topic partitions and cluster caps. Match or modestly trail partition count. - Data quality gates:
max_error_number/max_filter_ratiopause the job when bad rows exceed thresholds - useful for protecting SLAs.
If BE logs show batches ending on max_batch_size first, increase it to better fill the interval.
Hands-on: a resilient, exactly-once Routine Load
1) Table for events
CREATE TABLE rt_events (
  event_time   DATETIME,
  user_id      BIGINT,
  action       VARCHAR(32),
  attr_json    JSON
)
DUPLICATE KEY(event_time, user_id)
DISTRIBUTED BY HASH(user_id) BUCKETS 32;
2) Job with sane defaults and tolerant JSON parsing
CREATE ROUTINE LOAD app.rt_events_rl ON rt_events
PROPERTIES (
  "desired_concurrent_number" = "8",
  "max_batch_interval" = "10",
  "max_batch_rows"     = "500000",
  "max_batch_size"     = "536870912",   -- 512MB
  "format"             = "json",
  "jsonpaths"          = "[\"$.event_time\",\"$.user_id\",\"$.action\",\"$\"]",
  "strict_mode"        = "false"        -- tolerate minor type drift
)
FROM KAFKA (
  "kafka_broker_list"       = "broker1:9092,broker2:9092",
  "kafka_topic"             = "events",
  "kafka_default_offsets"   = "OFFSET_BEGINNING"  -- or a timestamp
);
Exactly-once semantics apply automatically for JSON/CSV Routine Load.
3) Operational playbook
- Check health/lag:
SHOW ROUTINE LOAD FOR app.rt_events_rl\G; SHOW ROUTINE LOAD TASK FOR app.rt_events_rl\G;shows consumed offsets and per-partition lag; alerts can scrape these. - Backfill one hour from yesterday:
ALTER ROUTINE LOAD app.rt_events_rl FROM KAFKA ("kafka_offsets" = "0:12345,1:67890,2:54321");or recreate withkafka_default_offsets='2025-11-19 10:00:00'. - Throttle during hot hours:
ALTER ROUTINE LOAD app.rt_events_rl PROPERTIES ("desired_concurrent_number"="4","max_batch_interval"="20"); - Safe interventions:
PAUSEfor maintenance,RESUMEto continue from last commit,STOPis final (recreate to ingest again).
Designing SLAs that mean something
- Latency SLA (ingest-to-visible): target P95 task commit latency (batch close + commit). Tune
max_batch_intervalfirst; don't over-optimize row/byte limits. - Freshness SLA (topic lag): alert on per-partition
LagfromSHOW ROUTINE LOAD. Scaledesired_concurrent_numberuntil lag stabilizes near zero during peaks. - Data quality SLA: set
max_error_number/max_filter_ratio. Failing noisily early beats silent corruption. - Recovery SLA: document the playbook for "offset out of range" (reset offsets or recreate with a timestamp). Keep Kafka retention comfortably above your MTTD + MTTR.
Common pitfalls
- Microscopic batches (tiny
max_batch_interval) → high commit overhead. Start at 10-60s; confirm throughput before lowering. - Concurrency > partitions doesn't help; match partitions first.
- Manual pause without a plan leads to expired offsets. If pausing, ensure Kafka retention safely covers the downtime.
- Assuming schema changes "just work" - for model changes use schema change; for transient drift use loader properties.
TL;DR
- Use Routine Load for continuous Kafka → Doris ingestion with exactly-once guarantees.
- Control offsets at creation (
kafka_default_offsets, timestamps) and adjust withkafka_offsets. Inspect lag viaSHOW ROUTINE LOAD. - Tame backpressure with
max_batch_*anddesired_concurrent_number. - Handle schema drift via JSON options and tolerance flags; apply a schema change for real model evolution.
Further reading
- Apache Doris - Routine Load manual (overview & examples)
- CREATE ROUTINE LOAD (all properties, including time-based offsets)
- ALTER ROUTINE LOAD (change concurrency, JSON settings, explicit offsets)
- SHOW ROUTINE LOAD / SHOW ROUTINE LOAD TASK (monitor lag & progress)
- Schema Change (table evolution)
- Routine Load internals (batching/concurrency logic, exactly-once details)
Leave a Comment