Idempotent Ingest in QuestDB: WAL Deduplication and UPSERT KEYS
Replaying a Kafka topic after a bad deploy is a classic way to create duplicates. The pipeline restarts from T-30 minutes "to be safe," dashboards spike, and alerts fire on rows that should have been a single event. QuestDB's deduplication on WAL tables lets you replay safely and keep a single canonical row per event: send the data again, and the database reconciles it on write.
What "idempotent ingest" means in QuestDB
Idempotent ingest means you can write the same logical events more than once and end up with exactly one canonical row per event. QuestDB implements this at the storage level for WAL tables using deduplication with UPSERT KEYS:
- You tell QuestDB which columns uniquely identify an event (the UPSERT KEYS).
- On insert, QuestDB replaces any existing row that matches all those key columns (last-writer-wins).
- Dedup applies only to new inserts after it is enabled; it does not rewrite historical duplicates.
Boundaries: dedup works only on WAL tables, and the semantics today are last-writer-wins (skip/merge variants are on the roadmap).
Mental model
Picture a conflict check in front of the table partitions:
[Write-Ahead Log] --(conflict check on UPSERT KEYS)--> [Table Partitions by time]
                                   |
                           (match? replace : insert)
The WAL gives durability and concurrency; the dedup step checks your key set, then inserts or replaces.
Choosing good UPSERT KEYS
Pick a key set that uniquely identifies an event at the intended grain:
- IoT/metrics:
(ts, device_id)or(ts, metric, tag) - Trades/orders:
(ts, trade_id)or(ts, symbol, exchange, seq) - Logs:
(ts, source, line_hash)
Practical tips:
- Prefer
SYMBOLfor repetitive tags (device, symbol, region). It saves space and can be indexed for fast filters. - Do not key on floats that can drift (e.g.,
price). - Keep the key count minimal - more keys means more work per insert during conflict checks.
Enabling dedup (new or existing tables)
Create a new WAL table with dedup and keys
CREATE TABLE trades (
  ts       TIMESTAMP,
  symbol   SYMBOL CAPACITY 1024 CACHE,
  trade_id LONG,
  price    DOUBLE,
  size     INT
)
TIMESTAMP(ts)
PARTITION BY DAY
WAL
DEDUP UPSERT KEYS (ts, trade_id);WALensures durability and parallel ingest.DEDUP UPSERT KEYS (ts, trade_id)turns on last-writer-wins for those keys.
Turn on dedup for an existing WAL table
ALTER TABLE trades
DEDUP ENABLE UPSERT KEYS (ts, trade_id);- Works only if
tradesis a WAL table. - Does not clean historical duplicates; it applies to new inserts going forward.
Verify configuration:
SELECT column, upsertKey
FROM table_columns('trades')
ORDER BY column;
What actually happens
| You insert... | Keys | Result |
|---|---|---|
| A new event never seen before | (ts, trade_id) | Insert |
Same (ts, trade_id) with different fields | (ts, trade_id) | Replace existing row (last-writer-wins) |
| Multiple duplicates in the batch/stream | (ts, trade_id) | Table keeps one (the last) |
QuestDB checks for rows that match all UPSERT KEYS and replaces them with the new one.
Replays and backfills
Scenario: an ingest failure at 12:34. You fix the app and replay from 12:00 to cover missed data. With dedup enabled:
- It is safe to resend that window; duplicates are resolved on write.
- If a WAL table got suspended (disk full, OS limits), fix the cause and resume:
ALTER TABLE trades RESUME WAL;- or skip a bad transaction explicitly:ALTER TABLE trades RESUME WAL FROM TXN 5;. Monitor suspended tables via metrics.
Example: Python ILP plus replay loop
# pip install questdb
import time
from questdb.ingress import Sender, TimestampNanos

ILP_HOST, ILP_PORT = "127.0.0.1", 9009

def send_trade(sender, ts_ns, symbol, trade_id, price, size):
    sender.row(
        table="trades",
        symbols={"symbol": symbol},
        columns={"trade_id": trade_id, "price": price, "size": size},
        at=ts_ns
    )

# normal ingest
with Sender(ILP_HOST, ILP_PORT) as sender:
    send_trade(sender, TimestampNanos.now(), "AAPL", 123, 189.25, 100)

# later: replay a safe window (duplicates will be replaced)
replay_epoch_ns = TimestampNanos.now() - 30 * 60 * 1_000_000_000
with Sender(ILP_HOST, ILP_PORT) as sender:
    # idempotent resend; same trade_id at same ts will replace
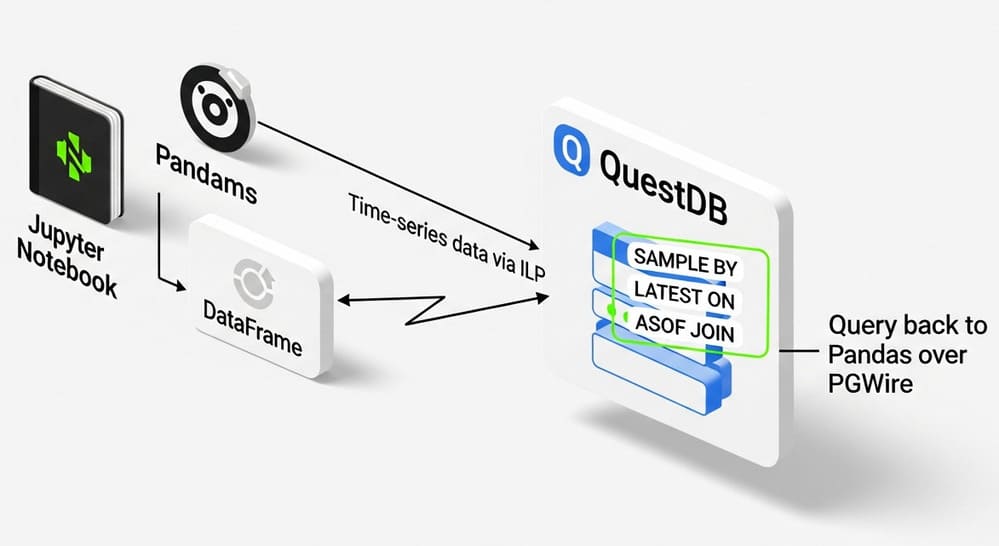
send_trade(sender, replay_epoch_ns, "AAPL", 123, 189.30, 100)- ILP is the recommended high-throughput ingest path; PGWire is best for querying.
Verification query:
-- Expect exactly one row for a given (ts, trade_id)
SELECT count() FROM trades WHERE ts = $1 AND trade_id = $2;
Performance: what to expect and how to tune
- Dedup adds work per insert; the cost rises with more UPSERT KEYS and higher conflict rates. Test with real replay patterns.
- Favor ILP for heavy ingest; keep PGWire for ad-hoc writes and reads.
- Use
SYMBOLfor tags; consider indexing frequently filtered symbols, and mind cardinality. - Monitor WAL health and apply latency (Prometheus metrics for suspended tables and apply rates).
Common pitfalls
- Not a WAL table: dedup will not work. Ensure
WAL(or convert at restart withALTER TABLE … SET TYPE WAL). - Wrong keys: if keys do not uniquely identify the event, you will replace legitimate distinct rows. Re-check data grain.
- Expecting retroactive cleanup: enabling dedup does not deduplicate old data - only new inserts. Use SQL to repair history if needed.
- Too many keys: each extra key increases comparison work; start with the minimal unique set.
End-to-end checklist
Schema:
TIMESTAMP(ts) PARTITION BY <granularity>WALDEDUP UPSERT KEYS (<minimal unique set>)
Ingest: use ILP clients for throughput; batch and flush appropriately.
Replay: re-send a fixed window with confidence; dedup will replace matches. If a table is suspended, RESUME WAL (optionally from a transaction) and monitor with Prometheus.
Takeaways
- Idempotency is non-negotiable for real pipelines; QuestDB provides a storage-level solution with WAL plus dedup.
- Pick UPSERT KEYS that truly represent event identity; start small.
- Use ILP for firehose ingest, replay with confidence, and monitor WAL health.
Leave a Comment