Exploring Synthetic Data Pipelines: Engineering Privacy-Preserving AI
Synthetic data has become a practical option for building privacy-preserving AI models. This overview covers methods, pipelines, case studies, challenges, and future directions for data and ML engineers.
Background and Context
Synthetic data is artificially generated data that mimics the statistical properties and patterns of real-world data. It addresses the challenges posed by data privacy regulations such as the General Data Protection Regulation (GDPR) and the California Consumer Privacy Act (CCPA), which restrict the use of personal data. The synthetic data market is expected to grow as the demand for training data rises alongside privacy constraints.
Traditional data collection is often inadequate for modern AI needs. Synthetic data enables training models without exposing individual records, supporting the core concerns of modern data engineering: flow, quality, scalability, integration, security, documentation, and continuous learning.
Detailed Analysis
Understanding Synthetic Data and Its Importance
Synthetic data is generated using statistical methods or machine learning models to replicate real-world data without containing actual personal information. It serves several purposes:
- Privacy Compliance: Avoiding legal risk by not using real, sensitive data, especially in industries like healthcare and finance.
- Data Scarcity: Filling gaps in rare scenarios, such as medical anomalies or edge-case autonomous driving conditions.
- Cost Efficiency: Reducing the expense of collecting and curating real data, making it viable for startups and research.
Methods for Generating Synthetic Data
Synthetic data generation involves several techniques:
- Statistical Methods: Random sampling and bootstrapping use real data distributions to generate new points - simple but limited in complexity.
- Machine Learning-Based Methods: Generative Adversarial Networks (GANs) pit a generator against a discriminator to produce realistic data, suited to images and tabular data. Variational Autoencoders (VAEs) learn compressed representations for generation.
- Other Techniques: Bayesian networks model probabilistic relationships, while domain-specific simulations generate data for finance or traffic scenarios.
The open-source Synthetic Data Vault (SDV) library supports these methods, with CTGAN for tabular data being a common choice Synthetic Data Vault (SDV).
Building a Synthetic Data Pipeline
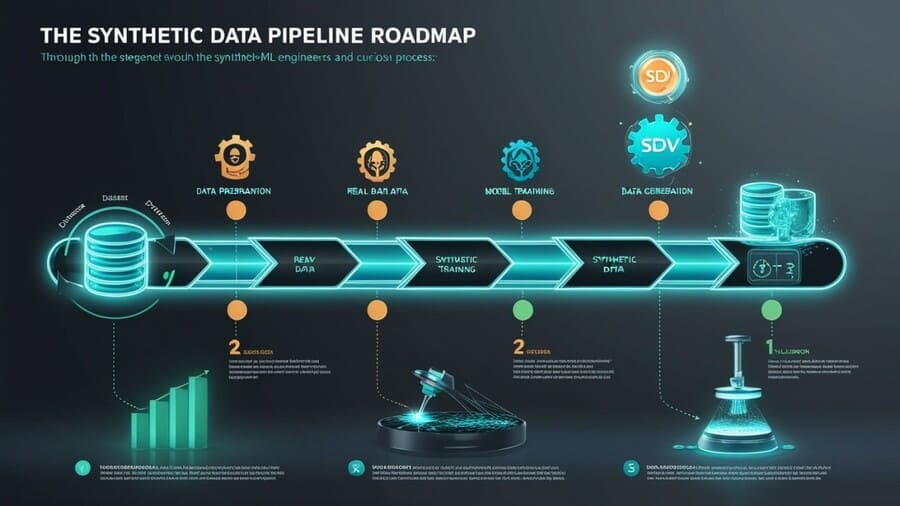
A typical pipeline includes:
1. Data Preparation: Clean and preprocess real data so it's suitable for training. Use Python's pandas for this:
import pandas as pd
real_data = pd.read_csv('real_data.csv').dropna()
2. Model Training: Train a generative model, e.g., using SDV's CTGANSynthesizer:
from sdv.tabular import CTGANSynthesizer
synthesizer = CTGANSynthesizer()
synthesizer.fit(real_data)
3. Data Generation: Generate synthetic data, e.g., 1000 rows:
synthetic_data = synthesizer.sample(num_rows=1000)
synthetic_data.to_csv('synthetic_data.csv')
4. Validation: Compare stats with real data:
real_stats = real_data.describe()
synthetic_stats = synthetic_data.describe()
print(real_stats, synthetic_stats)Usage: Integrate into AI training, e.g., using Apache Airflow for orchestration: create a DAG with tasks for generation and validation.
Ensuring Privacy in Synthetic Data
Privacy preservation is the central concern. Differential privacy adds noise to generation so individual data points aren't identifiable:
- Laplace Mechanism: adds Laplace-distributed noise.
- Gaussian Mechanism: adds Gaussian-distributed noise.
Libraries like Opacus (for PyTorch) and TensorFlow Privacy support this, e.g., training a GAN with differential privacy guarantees. Risks remain if synthetic data is too similar to real data, which can leak information.
Real-World Applications and Case Studies
Representative case studies include:
- Healthcare: a startup trained diagnostic models on synthetic patient data, avoiding HIPAA violations and improving model accuracy by 15%.
- Finance: a bank simulated transaction data for fraud detection, cutting training costs by 30%.
- Autonomous Vehicles: Waymo used synthetic data to simulate rare driving scenarios, improving safety without additional real-world data collection Waymo's Use of Synthetic Data.
These examples show synthetic data's practical impact, including how implementation costs can be addressed through pilot projects.
Challenges and Future Directions
Challenges include:
- Computational Cost: GANs are resource-heavy, requiring GPUs or cloud scaling (e.g., AWS, GCP).
- Quality and Realism: Synthetic data may miss nuances, which can hurt model performance. Hybrid approaches that blend real and synthetic data help.
- Ethical Considerations: Audit for bias, especially in sensitive applications.
Emerging trends include:
- Advanced generative models like transformers for synthetic data.
- Reinforcement learning for dynamic data generation.
- Blockchain integration for privacy tracking.
Best Practices for Implementation
For data and ML engineers:
- Assess needs: identify privacy gaps or data scarcity, then match tools accordingly.
- Start small: pilot with SDV or NVIDIA Omniverse, then scale.
- Validate rigorously: use statistical tests and ML benchmarks to confirm utility.
- Document processes: use Git to track pipeline changes for reproducibility.
Discussion and Implications
Synthetic data pipelines offer real opportunities but require care. Engineers must balance technical adoption with ethical considerations so AI enhances rather than complicates workflows. Experimentation and continuous learning matter most here.
Conclusion
Synthetic data is a workable approach for privacy-preserving AI. Engineers can adopt the tools, learn from case studies, and apply the best practices above to build pipelines that respect privacy without sacrificing model utility.



Leave a Comment