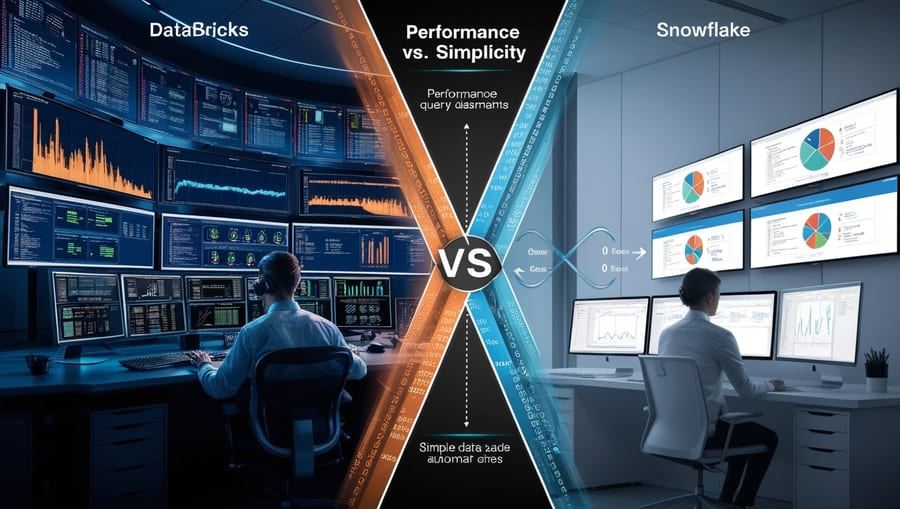
Vendors fight over benchmark wins, but the performance question that matters in practice isn't how fast a query runs - it's how much effort that speed costs, how predictable the bill stays as you scale, and whether the architecture fits your team. Databricks and Snowflake answer it from opposite philosophies. Databricks bets that data teams want control: the ability to tune and squeeze every ounce of performance from the infrastructure. Snowflake bets they want simplicity: automated optimization that delivers consistent performance without manual intervention. The choice is about which philosophy matches your team's capabilities and your tolerance for complexity.
The effort equation
Databricks is a high-touch performance machine - powerful, but it expects you to know how to drive it. Peak performance means a constellation of decisions: partitioning strategy (wrong columns scan too much data, too many create small-file problems), Z-ordering (powerful, but rarely worth it under ~1TB), Delta Lake maintenance (regular VACUUM and OPTIMIZE, careful statistics), and Spark configuration (memory, shuffle partitions, broadcast thresholds - dozens of parameters). For data growing 100GB/day, optimal performance requires choosing a partition strategy up front, scheduling ongoing OPTIMIZE/VACUUM, monitoring query patterns to adjust Z-ordering, right-sizing clusters, and transferring that knowledge across the team. Teams that master it achieve exceptional results - but it takes dedicated expertise and continuous attention.
Snowflake hides the complexity behind automation. Its micro-partitioned, multi-cluster architecture handles much of what's manual in Databricks: automatic partitioning by ingestion order with intelligent pruning, a cost-based optimizer choosing execution plans, auto-clustering that reorganizes data over time, and result caching that serves repeated queries instantly. The same 100GB/day workload simplifies to loading the data, letting clustering and optimization run transparently, and relying on auto-suspend/resume for cost - with standard SQL skills sufficient for most tuning. The trade is less granular control: you can't fine-tune every aspect of execution, but for many workloads the automated optimizations beat manual tuning attempts.
Architecture: smart engineering vs. brute force
Snowflake's edge comes from prioritizing efficiency over raw power - vectorized columnar execution, a cost-based optimizer that reads statistics and join patterns, and micro-partition metadata that lets the engine skip whole sections of a table. A telling benchmark: on a skewed join, Snowflake's 64 cores outperformed Databricks' 224 cores by 20% - not better hardware, but query planning that minimized unnecessary data movement. Databricks' Photon engine, written in C++ rather than Java, achieves impressive throughput for well-tuned large-scale processing, complex CPU-intensive transformations, and streaming. But it tends to need more compute than Snowflake for comparable BI workloads, the optimization overhead doesn't pay off on small-to-medium datasets, and ad-hoc interactive queries benefit more from intelligent pruning than from raw processing power. A data-ingestion test makes the point: a single CSV-parsing configuration change in Snowflake dropped ingestion from 67 seconds to 12, far ahead of Databricks' single-threaded CSV approach - Snowflake is optimized for common tasks out of the box, while Databricks rewards thoughtful configuration.
Cost dynamics
Snowflake's serverless model produces predictable costs: warehouses auto-suspend when idle (even a 512-node warehouse scales to zero cost), scaling up or down keeps the performance-to-cost relationship linear, and shared storage lets multiple warehouses read the same data without duplication. Databricks' DBU-based compute is more complex: hitting consistent SLAs often means oversized clusters and higher baseline cost, different workload types (batch, streaming, ML) tend to need separate specialized clusters (resource sprawl), and the optimizations that make it shine - pre-warmed clusters, reserved capacity - demand upfront capacity planning. For a team running daily batch (4h), sporadic interactive analytics (8h), and weekly ML training (2h), Snowflake runs a single auto-suspending warehouse with per-second billing and no idle cost, while Databricks runs separate clusters with idle time between workloads and constant optimization to minimize waste.
Workload fit
Snowflake excels at SQL-first analytics (BI, financial reporting), compliance-heavy environments (column-level security, dynamic masking, audit trails, certifications), data sharing without copying, and semi-structured data via the VARIANT type for JSON and Avro. Databricks excels at streaming and real-time pipelines (its Spark roots), the full ML lifecycle (MLflow, Unity Catalog, notebooks), unstructured data (image, NLP work in Python and Scala), complex custom data engineering needing fine-grained control, and engineering-heavy teams that can exploit its flexibility.
The hidden cost of complexity
Databricks carries an engineering tax: maximizing performance requires expertise in Spark optimization, Delta Lake practices, cluster management, Python/Scala, and distributed-systems troubleshooting, plus ongoing monitoring, right-sizing, and dependency management - and implementations often depend on specialized knowledge held by individuals, so performance can degrade when those experts leave. Snowflake charges a simplicity premium instead: performance comes from widely-available SQL skills (easier hiring, lower knowledge-transfer risk), automatic optimization frees time for analysis over tuning, and consistent performance reduces the testing needed when deploying new workloads. A useful way to frame it:
Real performance = (query speed × consistency) ÷ (engineering effort + maintenance + cost variability)By that measure Snowflake often delivers better "real performance" even when raw query times are similar, because the denominator - total effort and complexity - is much smaller. The successful teams optimize for predictable scaling and ROI rather than maximum throughput.
Choosing - and the hybrid reality
Snowflake makes sense for SQL-heavy analytical workloads, analyst-heavy teams with strong SQL but limited programming, regulatory-compliance needs, a demand for predictable cost and performance, and limited data-engineering capacity. Databricks excels for ML and AI, streaming and real-time processing, complex transformations and unstructured data, fine-grained performance control, and large, programming-strong engineering teams building differentiated data products. Many organizations don't choose exclusively: Databricks for data engineering, ML training, and streaming; Snowflake for BI, reporting, and data sharing - playing each platform to its strengths.
Before deciding, assess honestly: can your team handle Databricks' tuning requirements, or does Snowflake's automation save more than it costs? Does your budget tolerate Databricks' potential for cost sprawl, or do you need Snowflake's pricing clarity? Is your primary need SQL analytics or Spark-based engineering? And how will your workload patterns change as you scale? Performance in 2025 is about intelligent scaling and ROI, not raw speed - and the platform that delivers the best real performance is the one that fits your context, not the one that looks best on a benchmark slide.
Comments (1)